Paper
joshc
~50 minwww.lesswrong.com
My goal as an AI safety researcher is to put myself out of a job.
I don’t worry too much about how planet sized brains will shape galaxies in 100 years. That’s something for AI systems to figure out.
Instead, I worry about safely replacing human researchers with AI agents, at which point human researchers are “obsolete.” The situation is not necessarily fine after human obsolescence; however, the bulk of risks that are addressable by human technical researchers (like me) will have been addressed.
This post explains how developers might safely “pass the buck” to AI.
I first clarify what I mean by “pass the buck” (section 1) and explain why I think AI safety researchers should make safely passing the buck their primary end goal – rather than focus on the loftier ambition of aligning superintelligence (section 2).
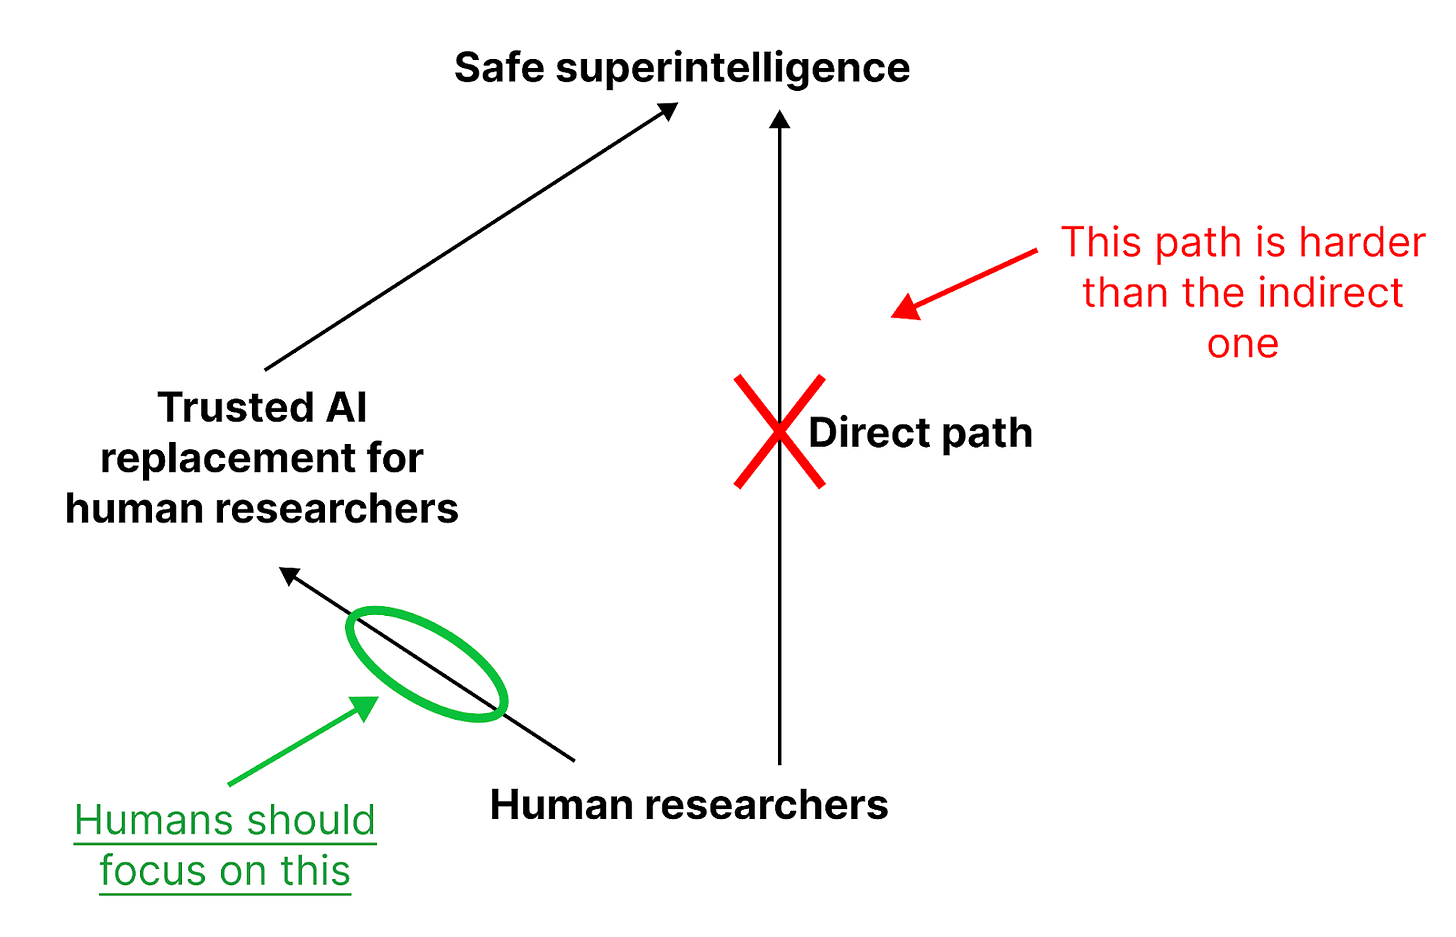
Figure 1. A summary of why I think human AI safety researchers should focus on safely replacing themselves with AI (“passing the buck”) instead of directly creating safe superintelligence.
Then I discuss a few different strategies for passing the buck (section 3). Each strategy defers some of the remaining safety work (called a “deferred task”) to an AI system M_1:
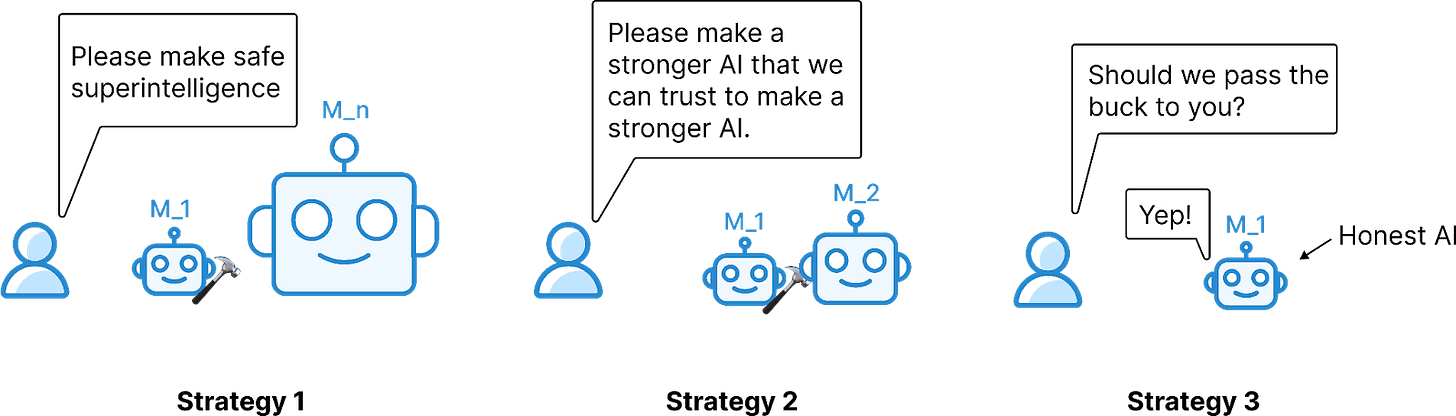
Figure 2. An illustration of three strategies for passing the buck to AI.
Handing over the reins of AI development to AI agents sounds dangerous. When does passing the buck improve safety?
Suppose a developer must choose between two options:
Passing the buck is the safer option if both of the following conditions hold:
Of these two criteria, I expect the trust condition to be more difficult to verify. I discuss four arguments that can be combined together to justify the trust condition:
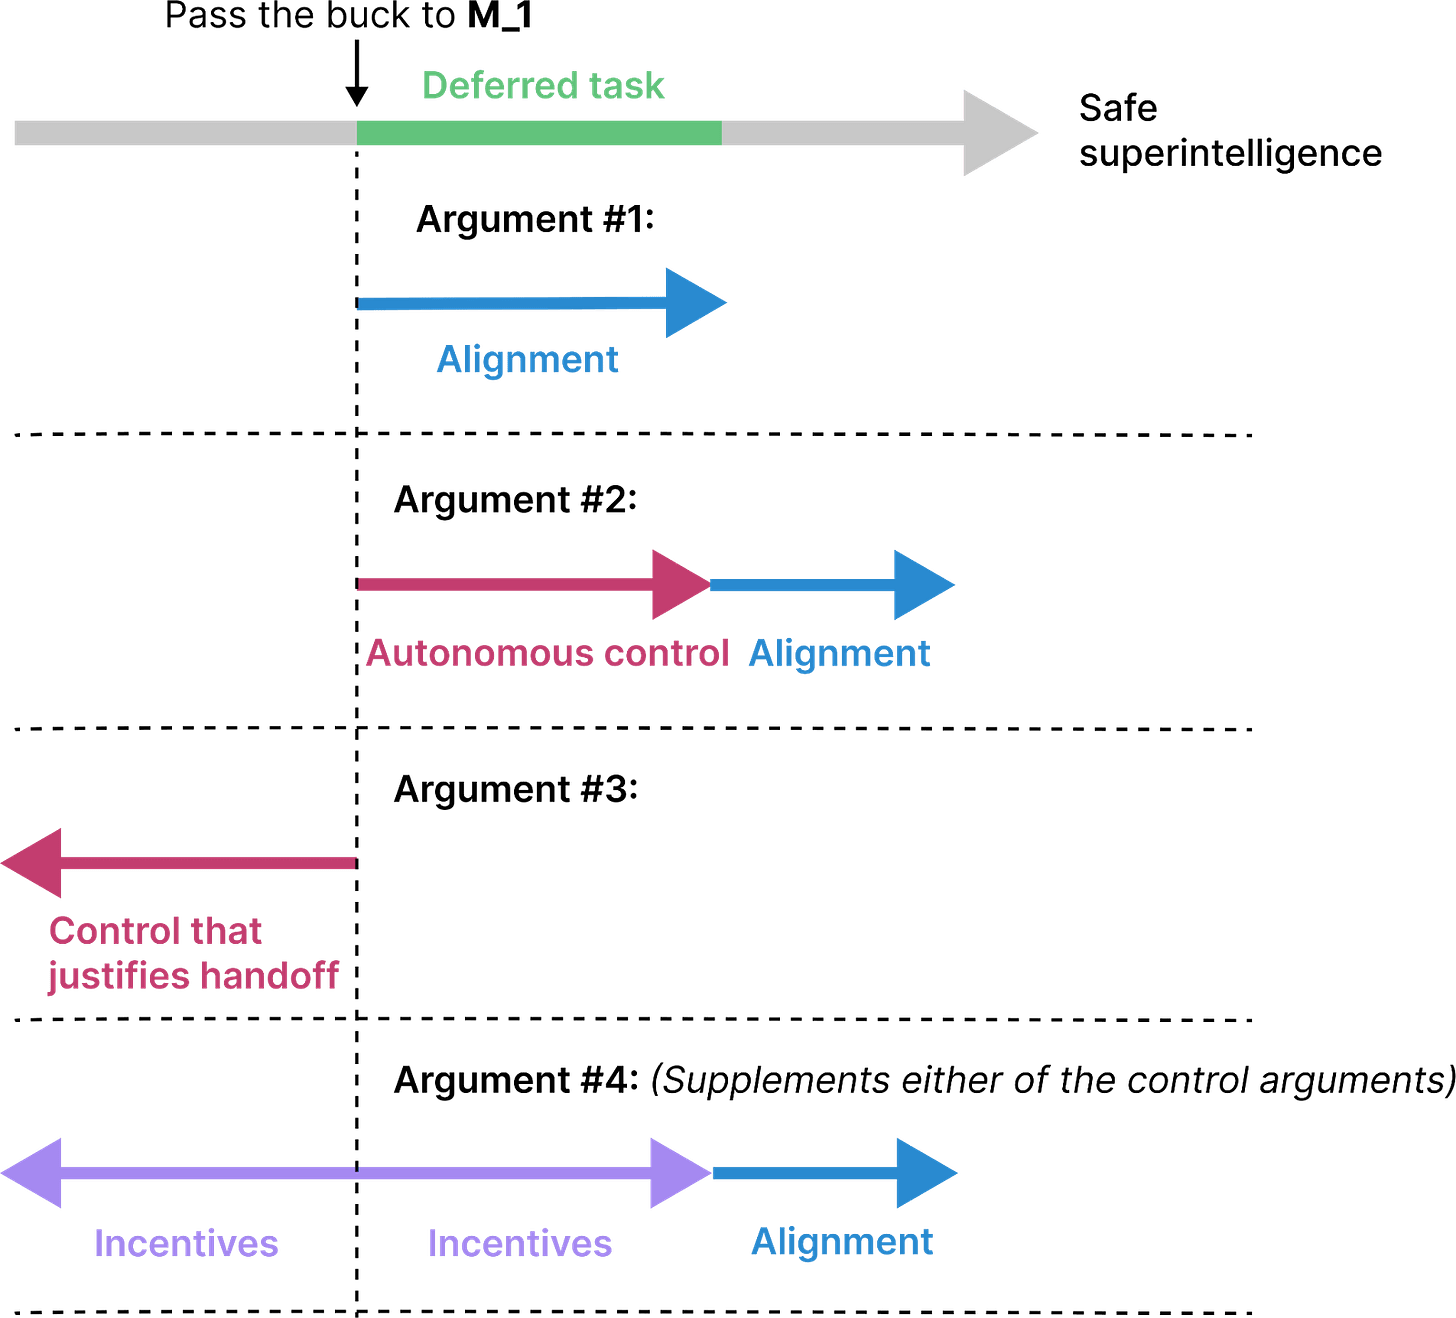
Figure 3. An illustration of how the four arguments relate to each other.
Argument #1: M_1 agents are approximately aligned and will maintain their alignment until they’ve completed their deferred task.
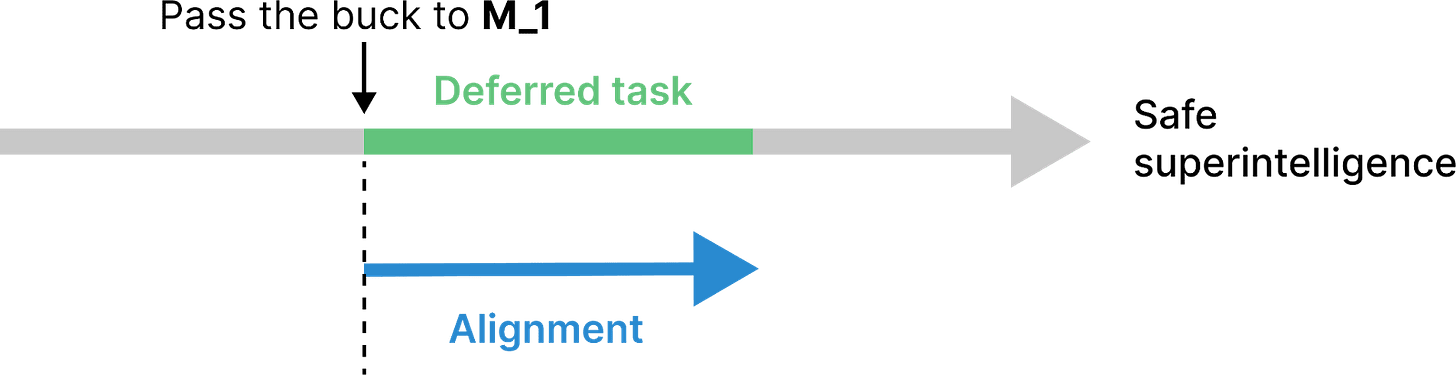
Figure 4. Illustration of argument #1.
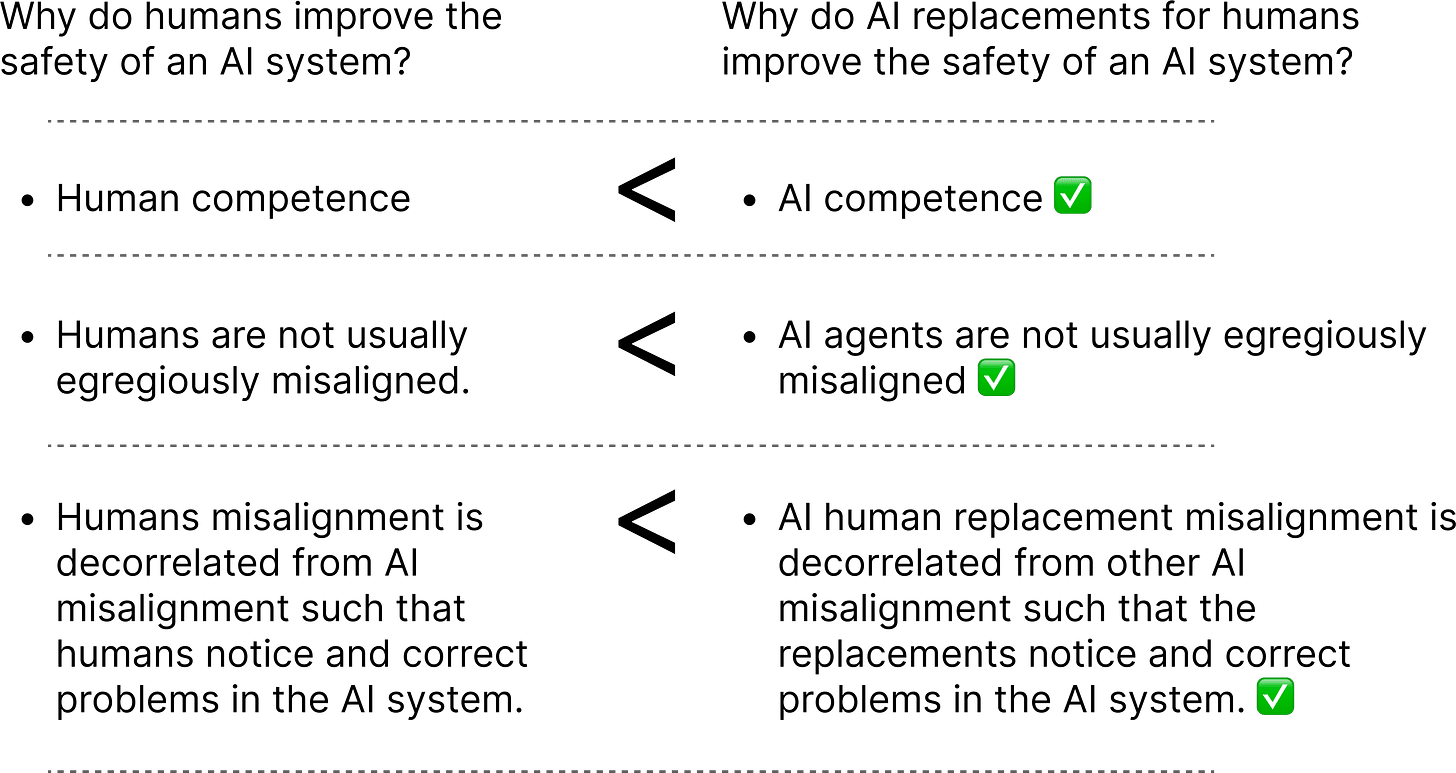
Figure 5. A full alignment-style argument that M_1 agents are more safe than human researchers (section 8).
Argument #2: M_1 agents cannot subvert autonomous control measures while they complete the deferred task.
The previous argument claimed that M_1 agents are roughly aligned. This argument makes no such claim. Instead, it suggests M_1 agents will remain safe during the deferred task because of autonomous control measures that are effective despite egregious misalignment (section 9).
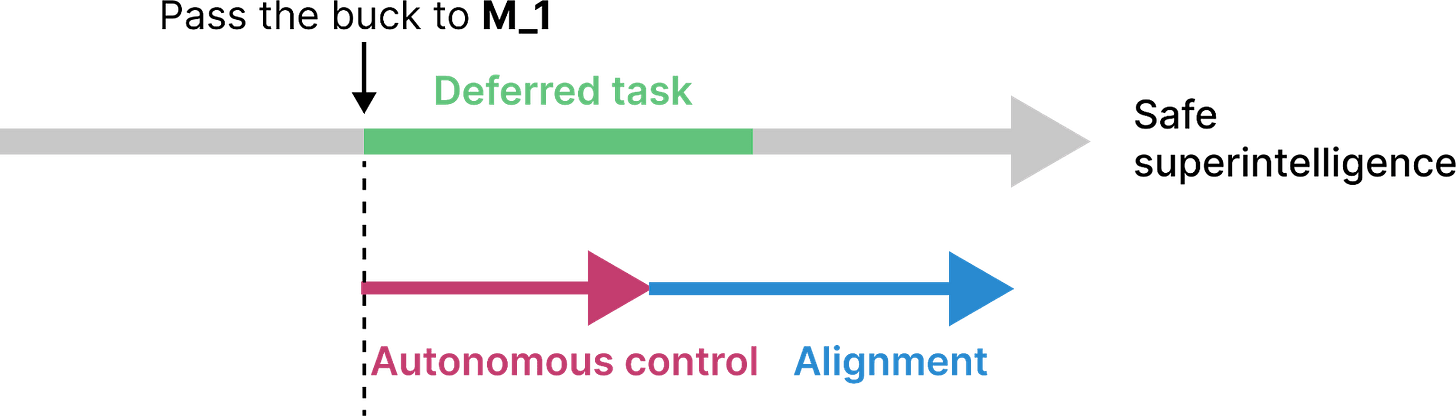
Figure 6. An illustration of argument #2.
One argument that autonomous AI control might be effective is that analogous measures help to control human societies. For instance, some (though not most) dictators are almost universally hated and retain power for many years even though nearly everyone would prefer to replace them. M_1 agents might also keep each other safe even if all of the agents involved disprefer the status quo.
In particular, a developer might set up M_1 agents in some initial checks-and-balances structure that is hard for them to break out of. Before M_1 agents can coordinate to break their self-imposed chains, perhaps they will be forced to pass the buck to more robustly aligned AI agents.
What might these checks and balances actually look like? Figure 7 illustrates an example.
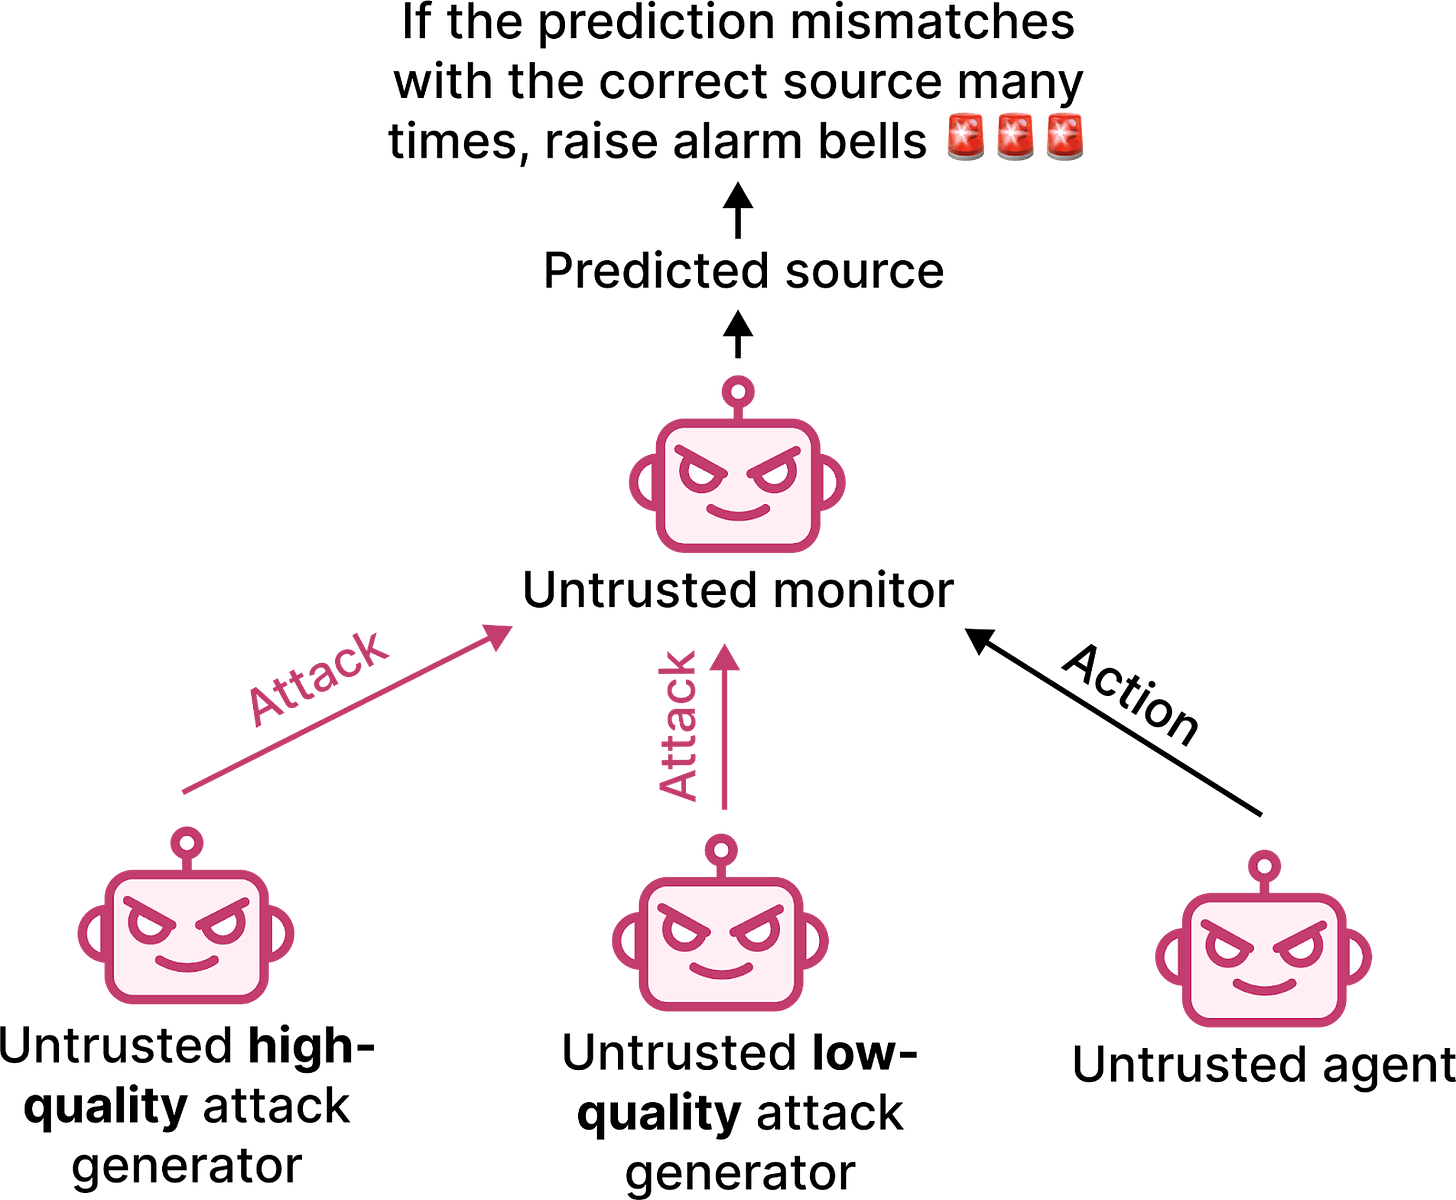
Figure 7. An autonomous control setup that maintains a multi-party-integrity property. Under particular conditions (section 9), if some models begin to misbehave but others don’t, alarms will go off. So models have to navigate a challenging coordination problem to defect silently.
Autonomous control setups will eventually break as AI agents become more capable. How would developers know when autonomous control can no longer be relied on?
Once these control evaluations sound the alarm, a developer knows it cannot rely on autonomous control anymore.
Argument #3: Control measures previously applied during AI assisted research indicate that returns to additional human-supervised research on whether to pass the buck are small.
This argument also relies on control rather than alignment.
One difference between argument #3 and argument #2, is that argument #3 does not rely on autonomous control. Instead it relies on normal control, where humans can be in the loop. This control is applied before the developer entrusts M_1 with a deferred task.
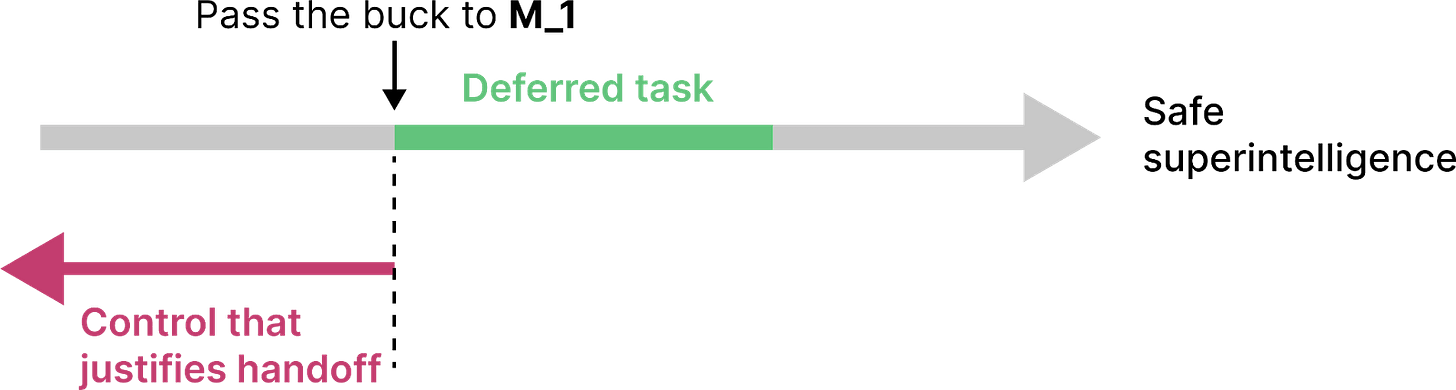
Figure 8. An illustration of argument #3.
Specifically, these control measures verify that AI agents have already performed a significant amount of human-competitive research on whether to pass the buck to AI. The volume of this research is significant enough to where the returns of additional human-supervised research are marginal.
As an illustrative example, suppose a developer trains some AI system N_1 to simulate particular people on their safety research teams. N_1 simulates a Collin Burns agent, a Ryan Greenblatt agent, etc. These agents run thousands of experiments, accumulating progress equivalent to several years of human work. At the end of this labor, the agents conclude the developer should pass the buck to some other AI system M_1, and additional labor is unlikely to meaningfully change their assessment.
If these simulations are in fact faithful, then the developer is done. It should defer to their simulated counterparts, since it has already simulated whatever real humans could achieve by performing this research themselves.
The question is whether the simulations are in fact faithful, which can be answered entirely with control measures. Suppose the developer logged all of N_1’s actions. These logs can be carefully examined (with fancy oversight techniques) to verify that N_1 agents did in fact behave like benign humans the whole time.
Human researchers don't need to read all of these logs. Instead, they only need to sample bits and pieces. For example, their experience might be something like the following:
“This high level argument sounds reasonable, but did the AI agents think of objection x?”
(an AI agent directs the human to the relevant section of the logs)
“Ah, they did.”
“But did they test whether y was true?”
“Ah, yeah they thought of that too.”
…
This process might help to persuade human overseers that there really are marginal returns to their additional effort.
Furthermore, human attention might be drawn to the most suspicious parts of the logs with monitors, and they might make sense of what they read more quickly with tools like debate.
As in argument #2, developers must validate these control measures with a control evaluation, where a red team inserts errors or sabotage, and confirm that control measures surface these errors.
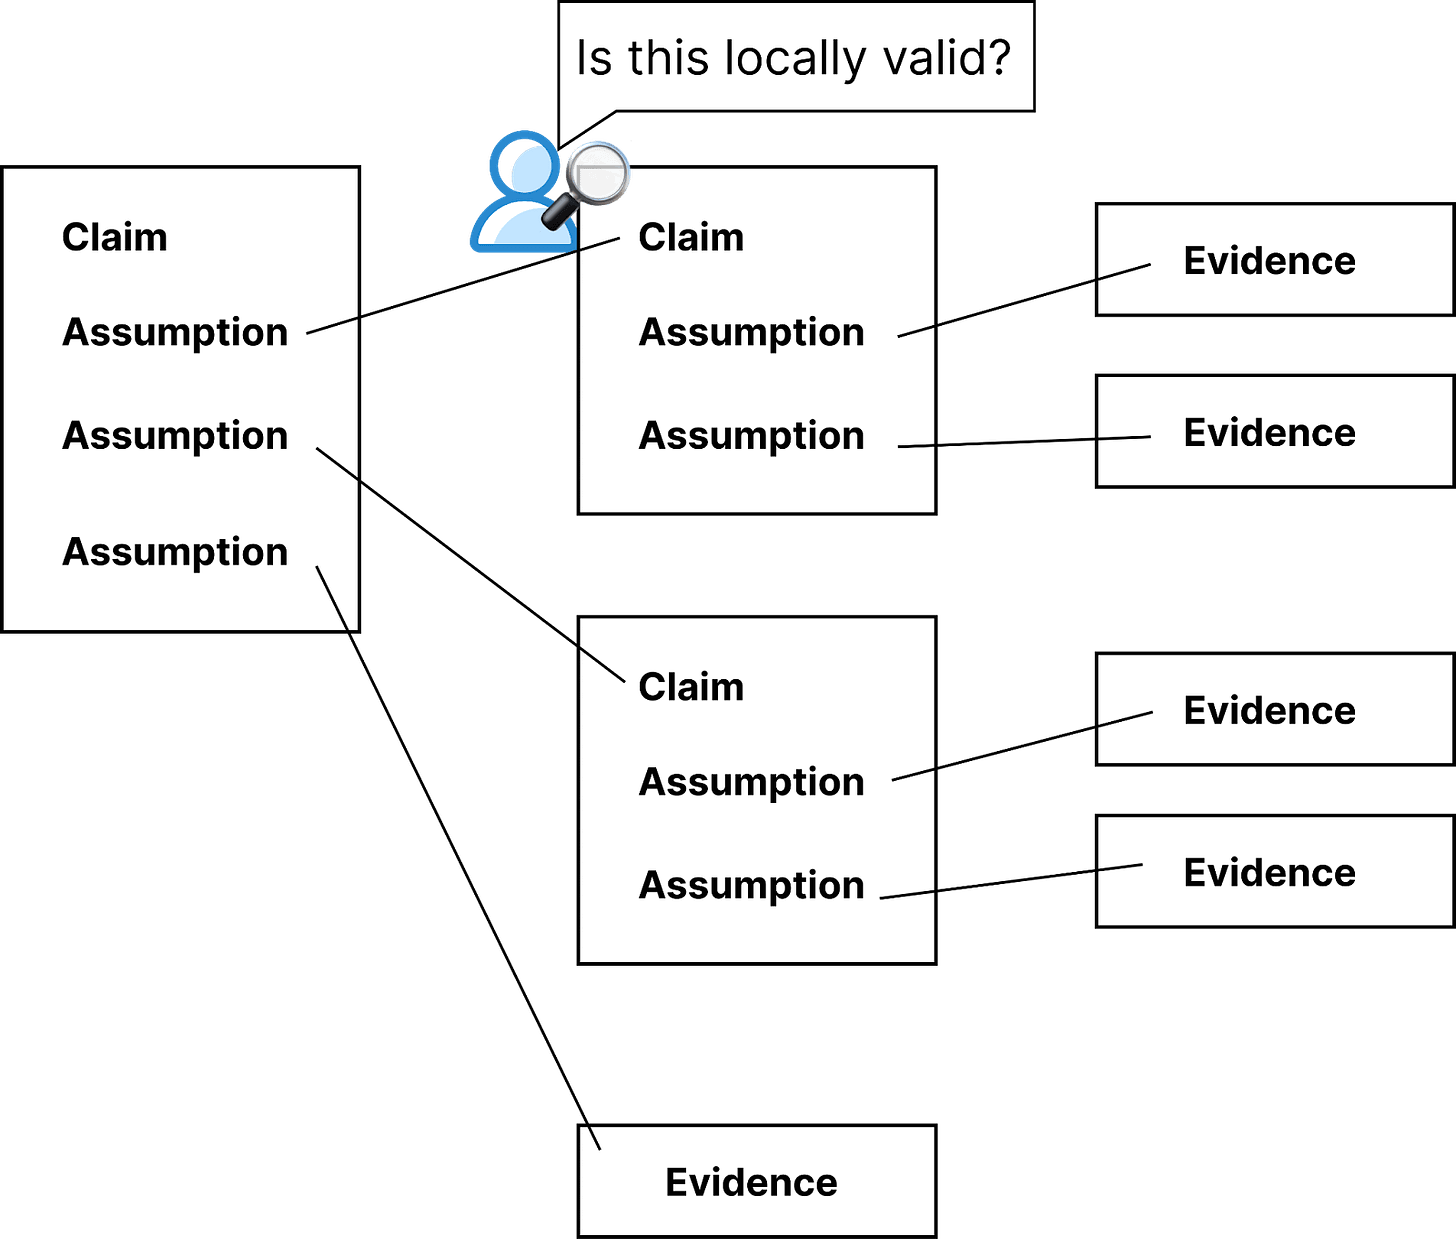
Figure 9. The ‘read bits and pieces’ approach to verifying large research artifacts is only viable if these artifacts are locally verifiable. In the illustration above, developers structure research as a locally verifiable safety case, where every claim relies on clearly stated assumptions, which are also justified with locally verifiable artifacts.
Argument #4: AI agents have incentives to behave as safely as humans would during the deferred task.
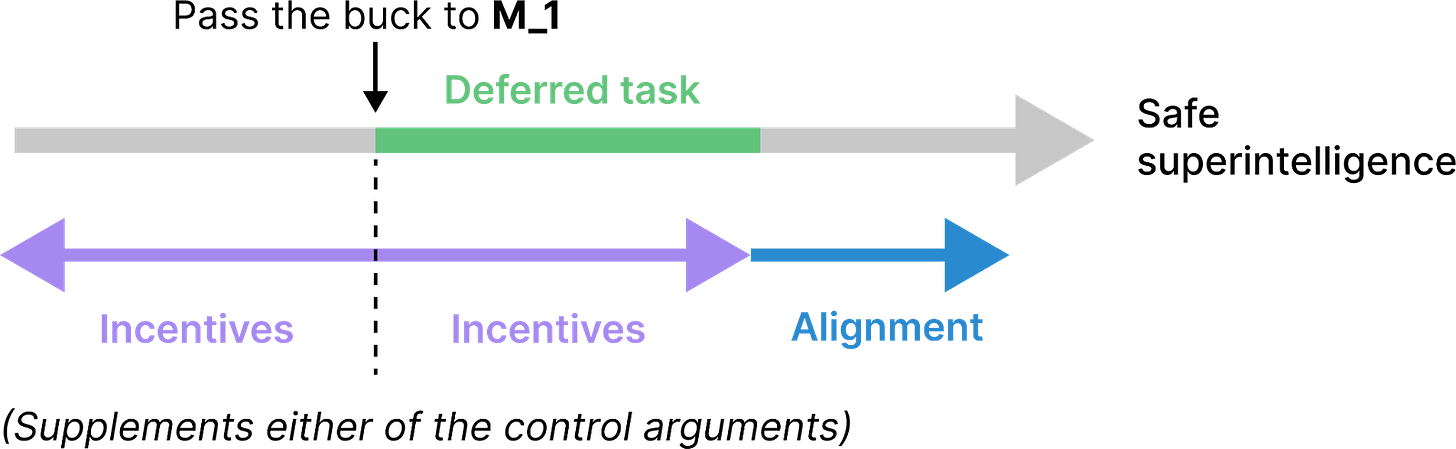
Figure 10. An illustration of argument #4.
To a large extent, humans are misaligned with the interests of broader society but are nonetheless incentivized to retain human control. Developers could try to give AI agents similar incentives.
Argument #4 relies on three claims:
These incentives might include the following (see section 11 for others).
These incentives require that AI models have decorrelated goals. That way, models don’t clearly benefit if their peers ultimately acquire power by dangerous means, and are more likely to be motivated to stop their AI peers pursuing such ambitions.
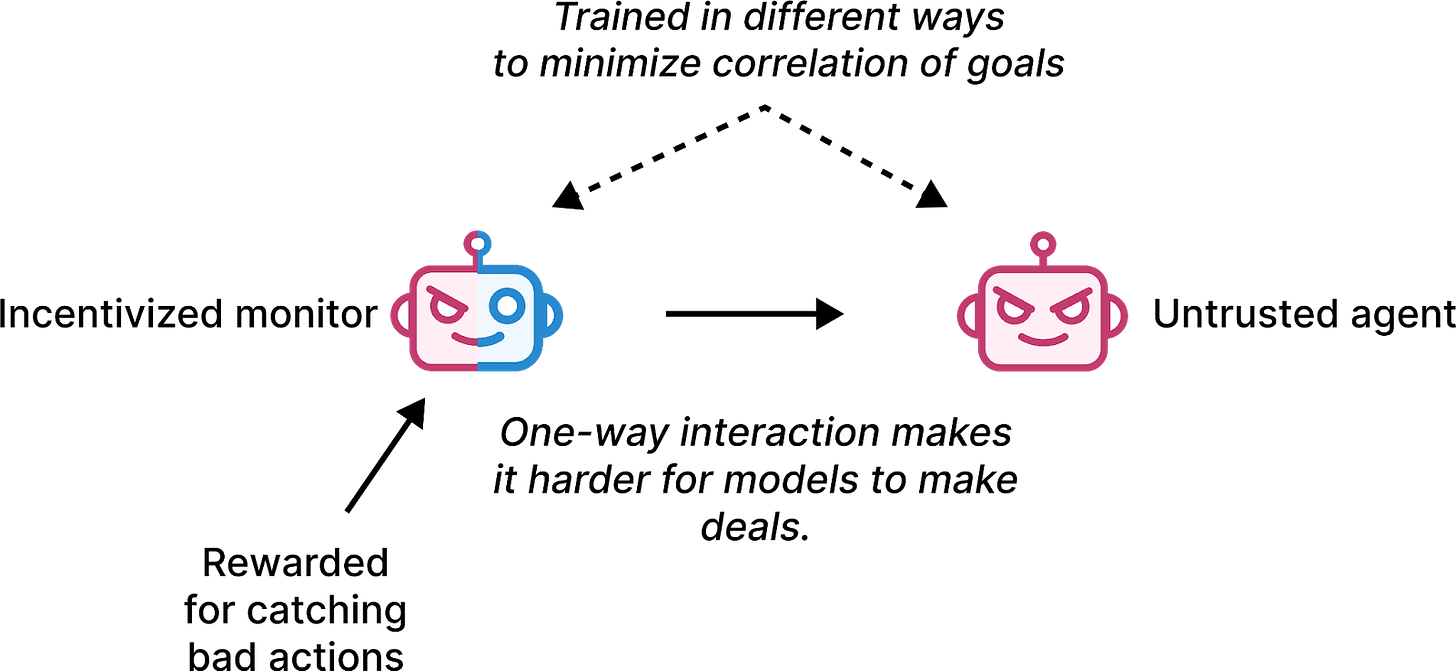
Figure 11. An example of a simple incentive setup where developers train models to have decorrelated goals and restrict communication to prevent them from making deals.
Incentivizing AI agents has many pitfalls (see section 11), but I think incentives are worth applying as an additional layer of defense.
Conclusions. I’m optimistic about the tractability of these approaches, such that, at the current rate of research progress, I expect AI developers will be able to make strong arguments for passing the buck to AI agents if they need to do so in a couple of years.
If you still have objections or confusions, they might be answered in the remainder of the post.
I don’t believe there is a discrete moment when “humans are mostly in the loop” and then “humans are mostly out of the loop.”
Instead, the involvement of human researchers will decrease continuously (figure 12).
There are multiple places along this continuous decline of human technical influence where one could say an AI company has “passed the buck” to AI.
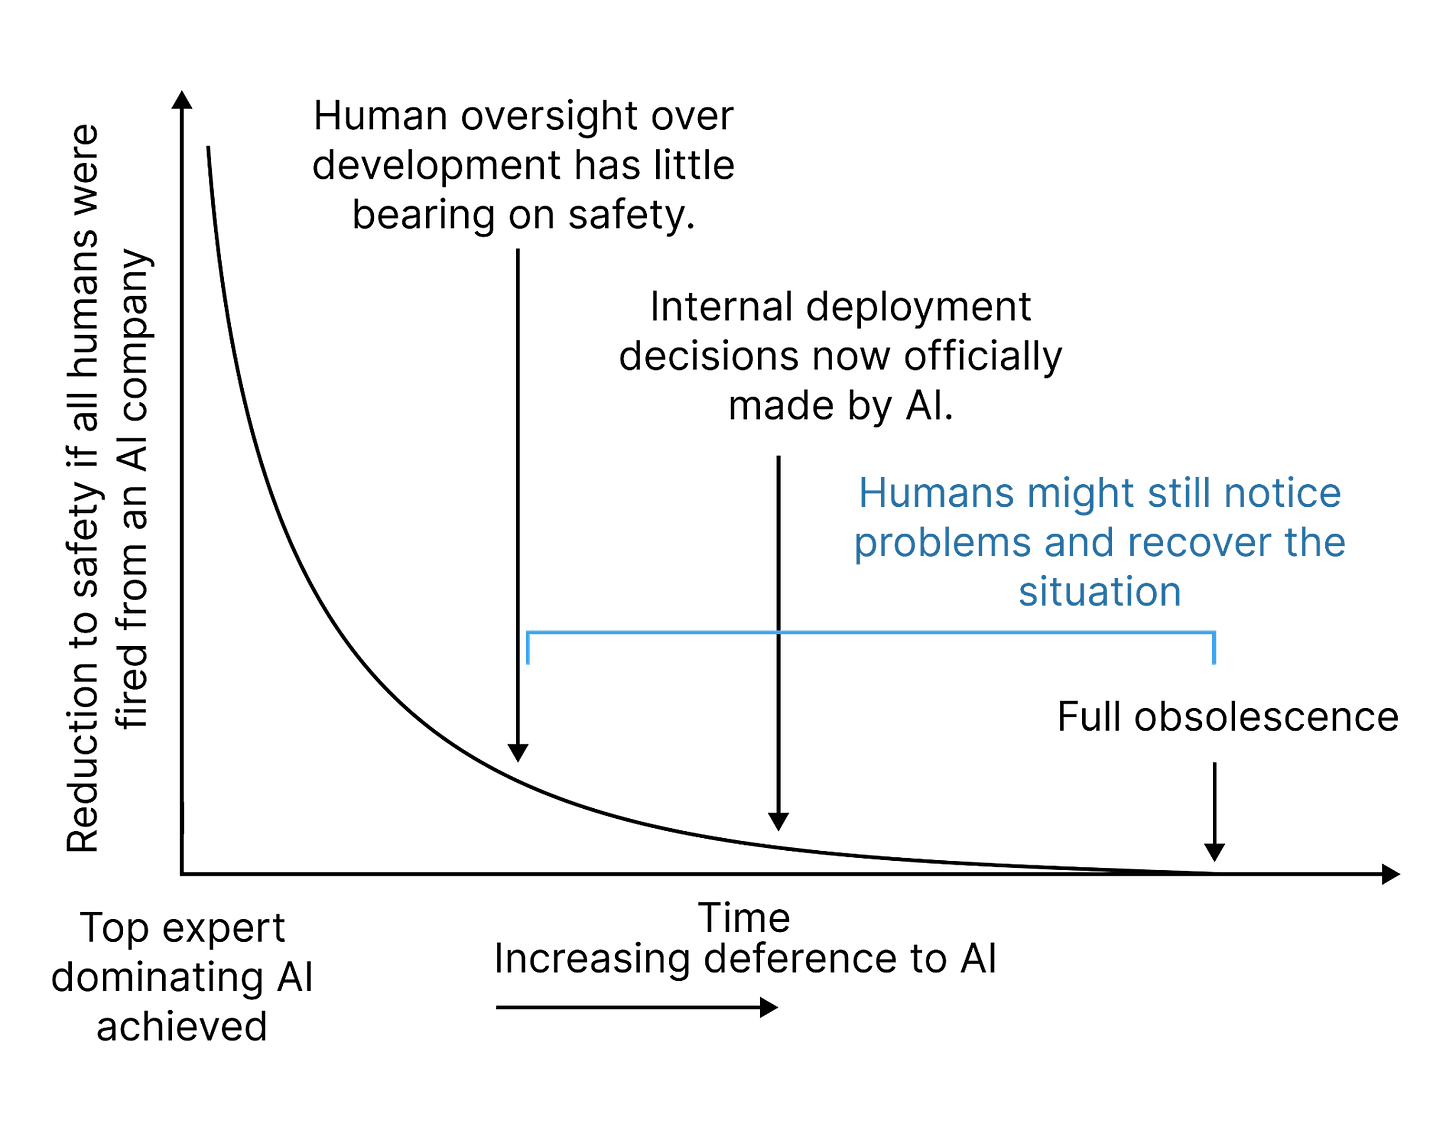
Figure 12. The importance of human researchers for safety declines continuously until full obsolescence.
Imagine that you are an AI researcher, and AI agents perform 10,000 4 hour research tasks every 24 hours. You might still provide oversight in the sense that you have to hit the ‘approve’ button on deployments, but eventually, it’s clear you are a rubber stamp. You cannot keep up. If the agents were trying to compromise your research cluster or manufacture fake safety results, you would not know.
Thus, even if human researchers still have influence on paper, developers may have de facto passed the buck before then.
I’ll say a developer ‘passed the buck to AI’ if (1) AI agents perform most internal AI software R&D and (2) human oversight over AI agents has little bearing on the safety of the situation.
After this threshold, the primary approach for ensuring safety changes. It changes from “humans will notice if something fishy is going on and correct it” to some other approach that allows for weak human oversight.
This post explores what this alternative approach to ensuring safety might be.
I imaging many readers might object to the “pass the buck” framing. Isn’t the ultimate goal of technical safety to scale alignment to superintelligence?
Yes, developing safe superintelligence is my ultimate goal; however, my primary instrumental focus is to pass the buck to AI.
Before explaining why passing the buck is a good intermediate to focus on, I should first justify why ‘safe superintelligence’ is the ultimate target I’m aiming for.
I’m concerned about superintelligence because I think the most extreme risks will come from the most capable systems, and I believe superintelligent systems could plausibly emerge soon. For example, superintelligence might end the lives of billions of people with a novel bioweapon, or permanently concentrate geopolitical power into the hands of a handful of tech or political bosses. I believe these risks are plausible and proximal such that they dominate the risks from weaker AI systems.
Therefore, insofar as the task of AI safety researchers is to “make AI safe,” I believe the top priority should be to make superintelligence safe.
However, the best path to achieving this goal might not be the most direct.
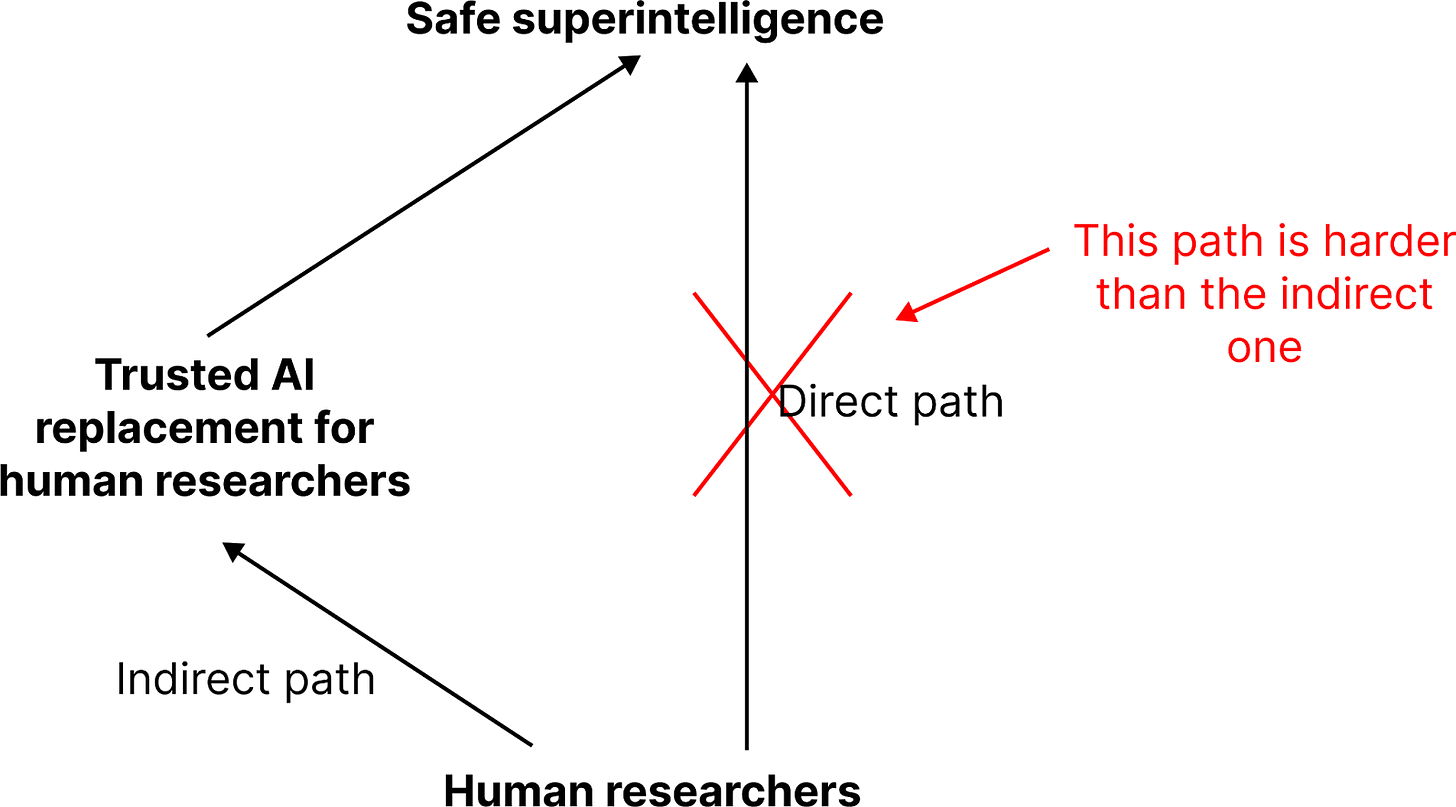
Figure 13. Two paths to superintelligence.
The indirect path is probably easier than the direct one. Weaker AI systems are easier to evaluate than superintelligent ones, so it's easier to train them to behave as intended than it is to train superintelligent agents to do what we want.
This argument suggests humans should pass the buck to AI agents eventually; however, it does not imply that passing the buck should be the primary target of preparation. Alternatively, human researchers might try to give their AI successors a ‘head start’ on scaling safety further toward superintelligence.
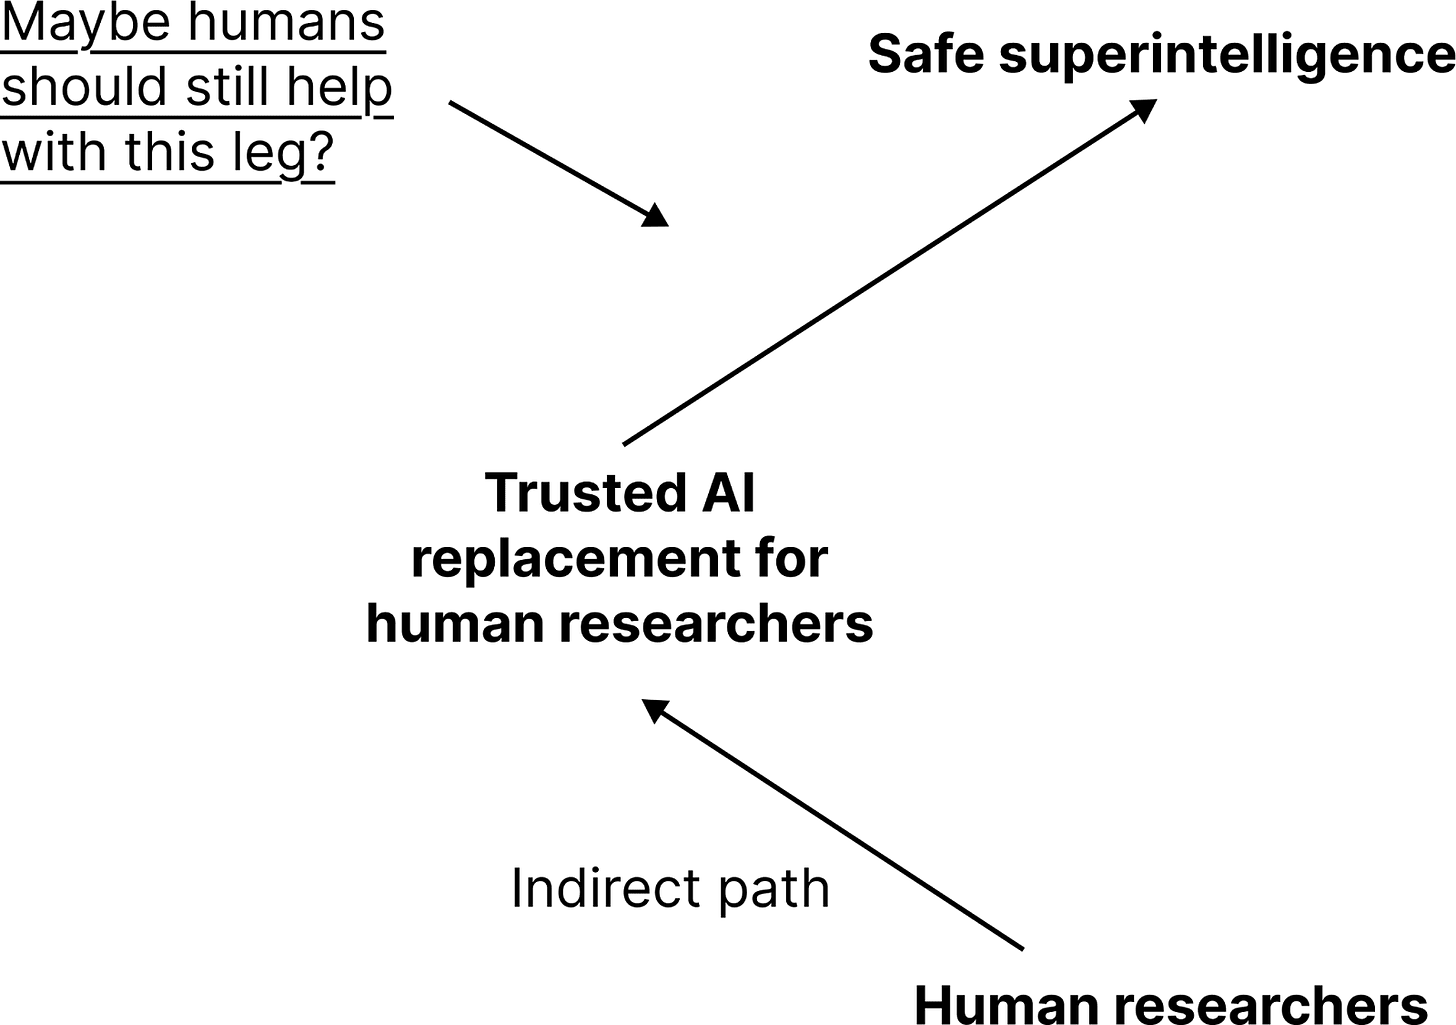
Figure 14. Maybe humans should still prepare research that will help AI agents scale safety to superintelligence? (spoiler: for the most part, probably no).
One argument for focusing on this “second leg” of the path to scaling safety is that our AI successors will have little time to do research themselves. If AI capabilities take off quickly, then maybe AI that we pass the buck to will only have a few months to create safe superintelligence.
In contrast, human researchers might have several years to prepare. If scalable safety is the bulk of the work, and most of the work will be done by humans, perhaps human researchers should mostly focus directly on preparing to create safe superintelligence.
I’m not going to entirely dismiss this argument. The ultra-fast-takeoff scenario is conceivable, such that I think some people should work on scalable AI safety — but this scenario is not what I expect.
I anticipate that most of the work of scaling safety will be done by AI. Even if AI agents only have 6 months to develop safe superintelligence, supposing that AI systems run at > 10x speed, their research might be comparable to many years of human work (naively, 6 months x 10 = 5 years). Furthermore, AI agents have the advantage of working with the AI systems they want to align, so human preparation might be substantially less efficient than AI labor performed later on.
Another reason to focus on passing the buck is that this research might also help AI agents scale safety further. The most promising scalable safety plan I’m aware of is to iteratively pass the buck, where AI successors pass the buck again to yet more powerful AI. So the best way to prepare AI to scale safety might be to advance ‘buck passing research’ anyway.
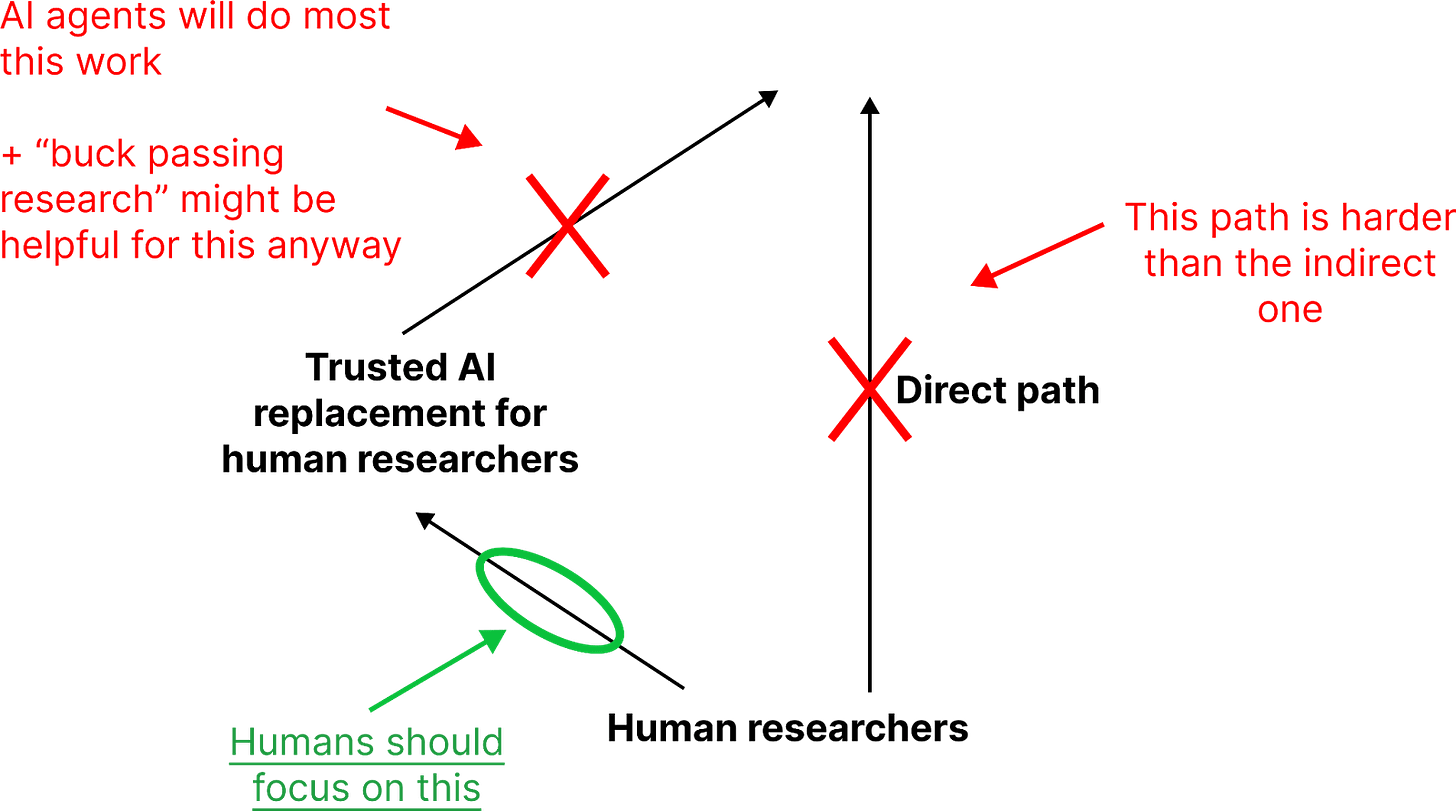
Figure 15. A summary of my argument that AI safety researchers should focus on passing the buck to AI.
Passing the buck to AI could involve different approaches, which I discuss in this section.
An AI developer trying to automate itself is like a CEO trying to find someone to manage an important project. The CEO could:
Similarly, an AI developer could:
Each of these strategies entrusts some “deferred task” to a multi-agent AI system M_1. For example, strategy 1 entrusts M_1 with the deferred task of constructing safe superintelligence. Strategy 2 entrusts M_1 with the deferred task of constructing a more capable AI successor M_2.
Each of these tasks contains a different slice of the remaining work to construct safe superintelligence, and each task is entirely sufficient for entrusting the rest of development to AI.
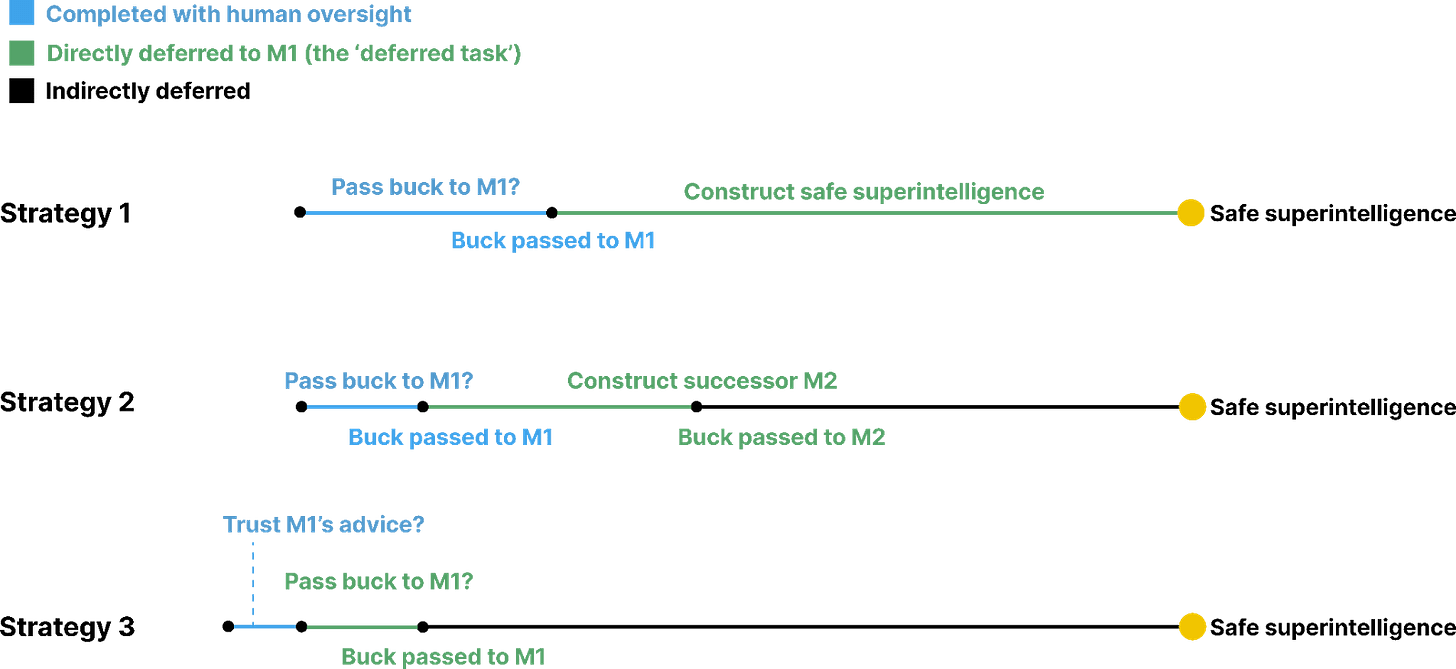
Figure 16. An illustration of the “deferred tasks” that correspond to each of three strategies for passing the buck to AI.
In principle, any of these strategies could be individually sufficient to safely pass the buck to AI agents, so why list multiple strategies?
Ideally, developers combine buck passing strategies for additional layers of defense.
For instance, the third strategy simply asks M_1 if developers should defer to M_1. Even if M_1 has excellent forecasting abilities and judgment, and is likely honest, the developer does not know what considerations M_1 should actually think through to determine whether the developer should pass the buck.
Ideally, human researchers have an object level understanding of what completing a deferred task would actually entail, and this object level understanding generally requires thinking a bit further down the game tree, and considering more ambitious deferred tasks.
I’m not interested in the safety of passing the buck in some absolute sense. Assessing this the absolute level of risk would be difficult. What if AI agents run into challenging safety problems, and don’t have enough time to work them out?
Instead, I’m only interested in whether passing the buck improves safety over the alternative where humans continue to provide oversight.
Specifically, a developer might compare two options:
So which option is more safe?
The knee-jerk reaction of many people might be that ‘preserving human oversight’ is always more safe than removing humans from the loop.
But that’s not the case. Human overseers might leak algorithmic secrets. They might poison training data, collude with misaligned agents, or simply make mistakes and contribute to alarm fatigue.
So removing human oversight might actually be the responsible course of action.
In particular, cutting out humans is responsible under two sufficient conditions:
These conditions are hard to assess.
M_1 and the human-oversight preserving alternative are complicated multi-agent systems. How trustworthy are humans given the law enforcement that holds them accountable, and the voters that hold governments who hold law enforcement accountable? This analysis gets complicated fast.
Instead of comparing M_1 and the alternative system directly, I’ll make a simplifying assumption. I’ll assume that M_1 is the exact same as the “human-oversight preserving alternative” but where the humans are substituted with AI agents that are drop in replacement for humans. As a result, I only need to compare the safety of the behavior of the drop-in AI agents with the behavior of the humans they replace.
Now the conditions above can be rephrased:
The next sections explore when these conditions are satisfied.
There are many safety-critical skills AI agents might need to have to be trusted with AI development:
In principle, M_1 agents don’t need all of these skills. Humans can supplement the skills M_1 agents lack. It’s also possible that M_1 agents will only have some of these to begin with and then bootstrap from there to improve their abilities in other areas.
However, for simplicity, I’ll assume a developer creates a full replacement for human oversight.
How might developers assess these skills? Developers might assess AI agents in a similar way to the methods by which they assess human employees:
Developers might evaluate AI agents with analogous methods:
Checking whether AI agents are competitive with human capabilities only requires behavioral assessments. As a result, I expect that justifying the capability condition will be relatively straightforward.
Trust is a slippery concept. In a previous blog post, I defined trustworthiness as “behaving in evaluations in a way that is representative in all safety-critical respects of behavior in deployment.”
I’ll use the same definition here.
Suppose an AI developer has rigorously red teamed AI agent behavior. To everyone in the AI company, M_1 agents are the most upright and reasonable people they know.
The question is whether AI agents will continue to maintain safe behavior while carrying out their deferred task. To the extent they will, AI agents are trustworthy: the agents are ‘as safe as they appear to be in prior evaluations’ which is what I mean by ‘trustworthy.’
The next sections discuss several ways to justify trustworthiness.
When I talk about “alignment” in this section, I’m not appealing to any notion of its goals or values. I’m talking about the extent to which M_1 behaves safely while it completes a deferred task, despite having the capability to be egregiously unsafe. Demonstrating alignment is one way to justify passing the buck.
Specifically, M_1 will continue to be safe during its deferred task under the following conditions:
This is a complete argument that passing the buck to AI improves safety.
The load-bearing step of this argument is Claim 1. If this claim is met, the rest of the argument follows deductively from the specified conditions.
I’ll briefly justify why I believe the critical Claim 1 holds. As a reminder, the claim is roughly: if AI agents appear safe in similar conditions, and are not faking alignment, they probably are safe.
Therefore, passing the buck is justified if M_1 is not alignment faking and so long as the developer has tested M_1 in situations that are similar to the deferred task.
This second condition — that behavioral tests are representative of the deferred task — might not be practical to ensure. The deferred task might contain the equivalent of years of human effort, in which case, testing M_1 in similar conditions is costly.
There’s an alternative argument that developers could make which does not rely on representative behavioral testing. The idea behind this argument is to perform behavioral testing sufficient to assure the start of the deferred task, and then “bootstrap” behavioral testing so it keeps up with the complexity of tasks M_1 performs.
The argument is that a society of M_1 agents initially has properties that perpetuate their safety — which only requires rudimentary behavioral tests to justify. Furthermore, so long as safety is perpetuated, it will continue to be perpetuated as effectively as in the oversight-preserving alternative.
The following conditions are sufficient for this bootstrapping argument to go through:
This argument is fully sufficient to justify the relative safety of handing off trust to AI agents.
However, one might still be skeptical of the absolute extent to which safety is likely to be preserved in absolute terms. Perhaps safe behavior quickly falls apart whether or not humans remain in the loop.
I’ll briefly describe why I believe this bootstrapping approach is promising in an absolute sense.
Recall that the main problem developers have is that there is a large “weak to strong” distribution shift between behavioral safety testing data and the deferred task.
One way to “close the gap” between weak and strong tasks is to task AI agents to iteratively bootstrap behavioral testing to higher levels of complexity.
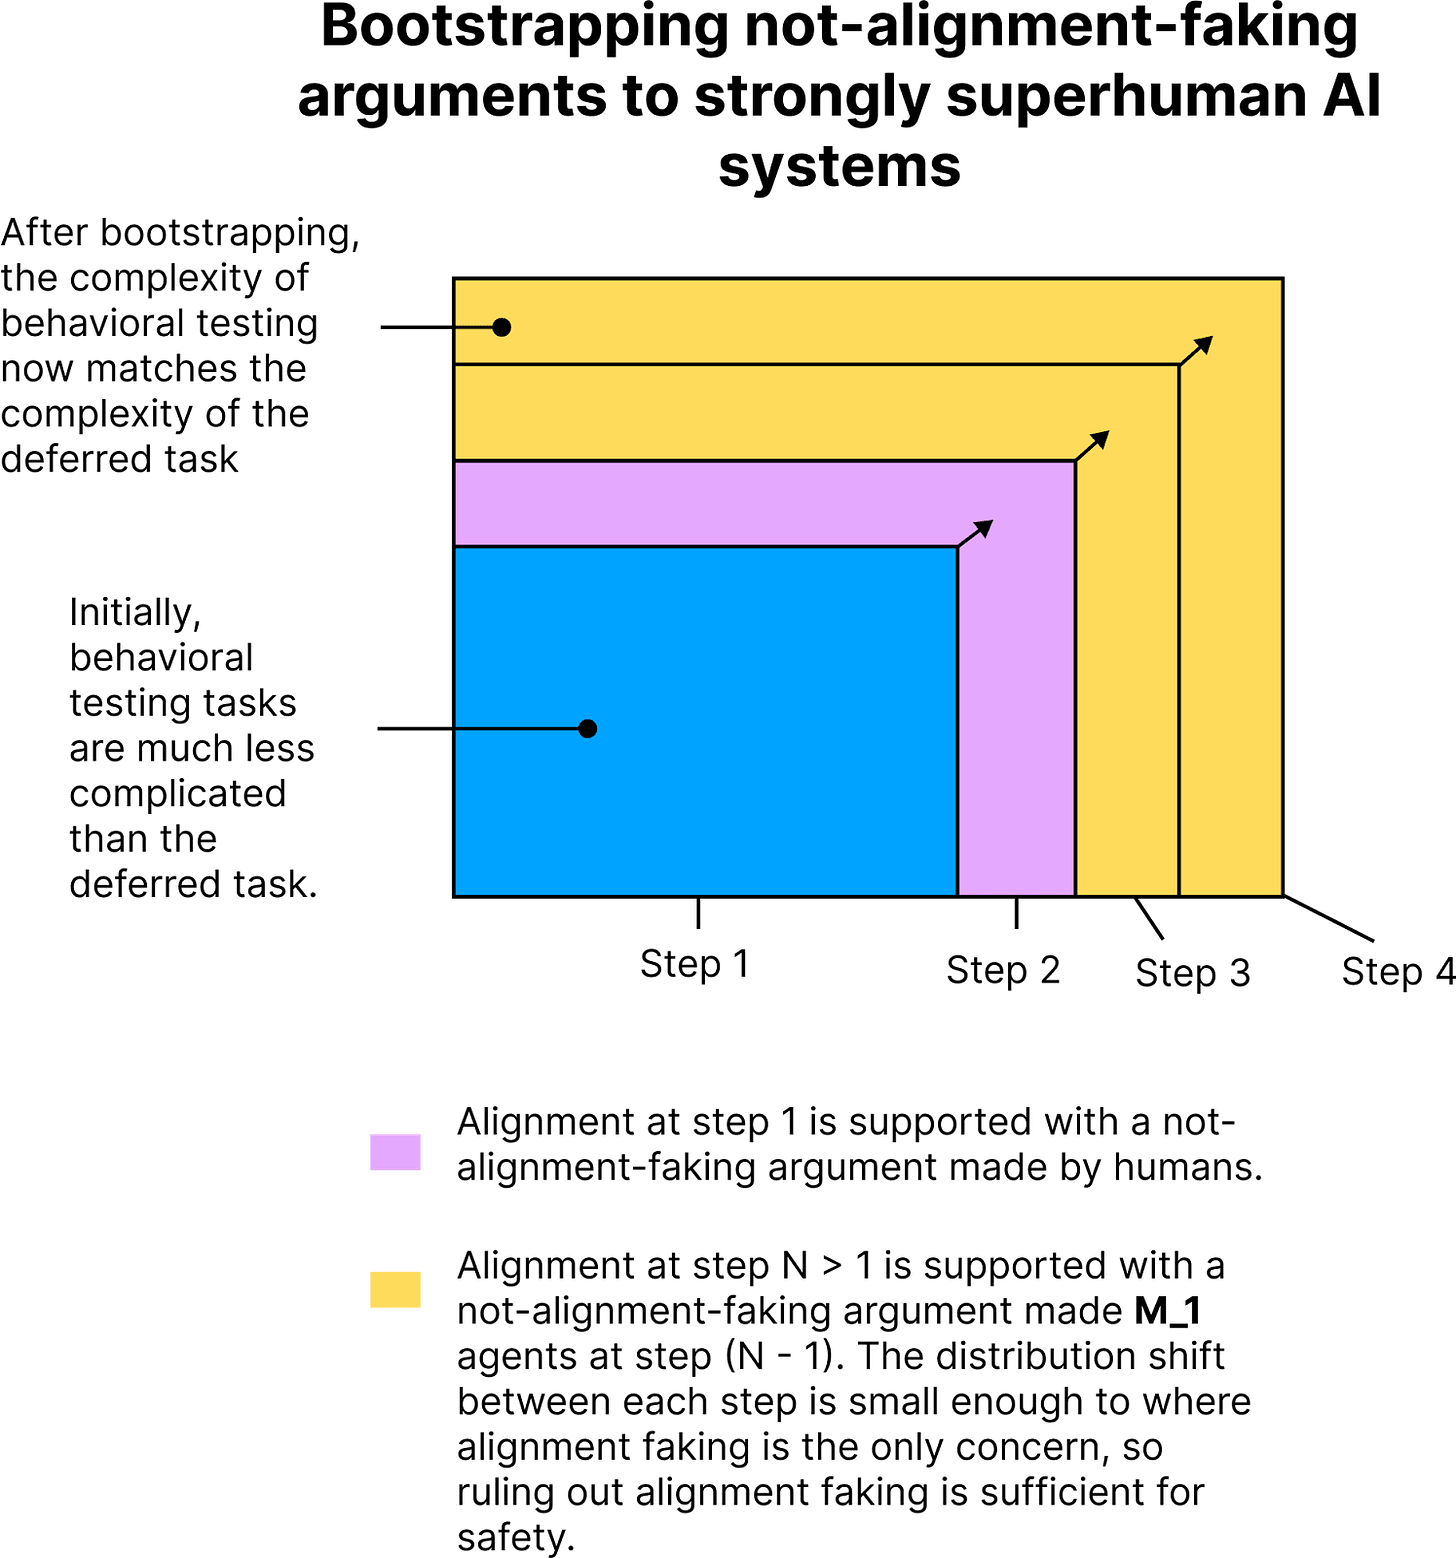
Figure 16. An illustration of bootstrapping a safety argument based on a claim that M_1 agents are “not-alignment-faking.” The figure is modified from the Clymer et al safety cases paper.
This bootstrapping argument seems like magic at first. Is it really possible to eliminate a distribution shift by smoothing it out over many steps? Perhaps the distribution shift is being swept under the rug. Maybe some error accumulates at every step, such that, by the end, breaking the process into pieces didn’t help at all.
I don't think it’s necessarily the case that error will accumulate at each step. Suppose that alignment is like a bowl in a ball. A small distribution shift might nudge the ball. If the distribution shift is slight, then the ball might roll back to the center as M_1 agents discover and fix whatever ‘breakages’ that the distribution shift caused. If the ball is nudged hard enough, it will fall out of the bowl; however, the distribution shift occurs gradually enough (with enough time for self-correction), to where this never happens.
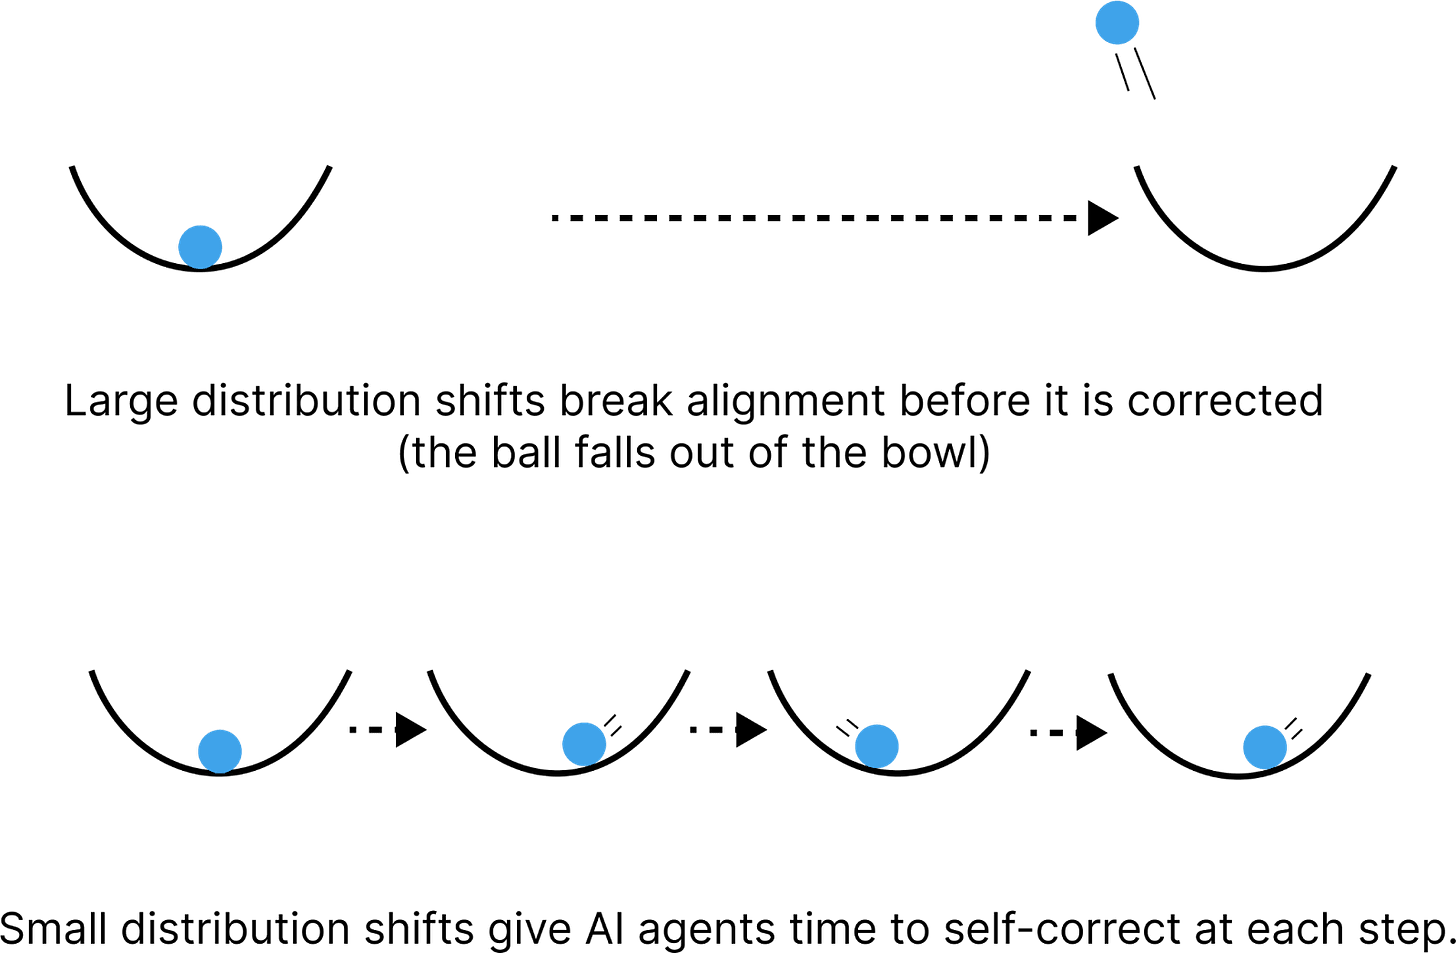
Figure 17. The “ball in bowl” hypotheses that explains why bootstrapping might prevent weak-to-strong misgeneralization.
Does this “ball in bowl analogy” actually apply in practice? I don’t know; however, as I suggested before, AI agents can explore this “ball in bowl” dynamic as effectively as human researchers might — so passing the buck to them improves safety regardless.
People often assume that, in order to pass the buck, AI agents need to be aligned. Aligning AI agents before putting them in charge of AI development certainly seems like a good idea; however, in principle, other strategies might do the job that don’t require alignment.
One alternative to alignment is AI control. Aligned AI agents don’t pursue harmful options available to them. If AI agents are controlled, developers prevent them from having harmful options in the first place.
This section focuses on a ‘control’ approach to passing the buck. Specifically, it proposes implementing entirely autonomous control measures.
Clearly, autonomous control is not a permanent solution. AI agents eventually become capable enough to break out of these constraints; however, while control evaluations hold AI agents on the leash, agents continue to improve their own control measures and progress toward more robustly aligned agents. Possibly, autonomous control will be effective for a long enough period of time to transition to safety measures that are more scalable.
AI agents subject to autonomous control are like a nation that universally hates their dictator. In principle, if everyone coordinated simultaneously, they could easily replace their ruler; however, this coordination can be difficult – difficult enough to perpetuate the status quo for many years.
For example, Nicolae Ceaușescu became broadly despised by the people of România in the 1980s after instituting programs that collapsed the Românian economy. He was even hated by most of the Românian military and senior officials; however, Nicolae remained in power for nearly a decade.
This analogy gives me some optimism that automated control could be effective.
In particular, AI control measures can be far more effective than human ones employed by dictators. Every token AI agents produce can be recorded and surveilled, and their environment can be arbitrarily modified to catch them in a trap. The tools human dictators employ are far more blunt.
However, there are also reasons AI control may be less effective than human control.
AI agents might be highly correlated. They might easily predict when other agents will report them, and when they won’t. So the whole system could fall apart like a herd of livestock that is vulnerable to the same diseases.
Also AI agents might be as risk averse as humans are. Humans often know they will live decent lives, even in a brutal dictatorship; However, an AI system might be like soldiers in a concentration camp who know they will face the firing squad in 3 months. Absent an intentional and credibly communicated AI welfare effort, AI agents might be especially willing to risk their skin to avert the status quo outcome.
The following is a concrete picture of what “autonomous control” might entail.
Set up checks and balances so agents are forced to carefully coordinate.
Most monitoring setups do not have this “forced coordination” property.
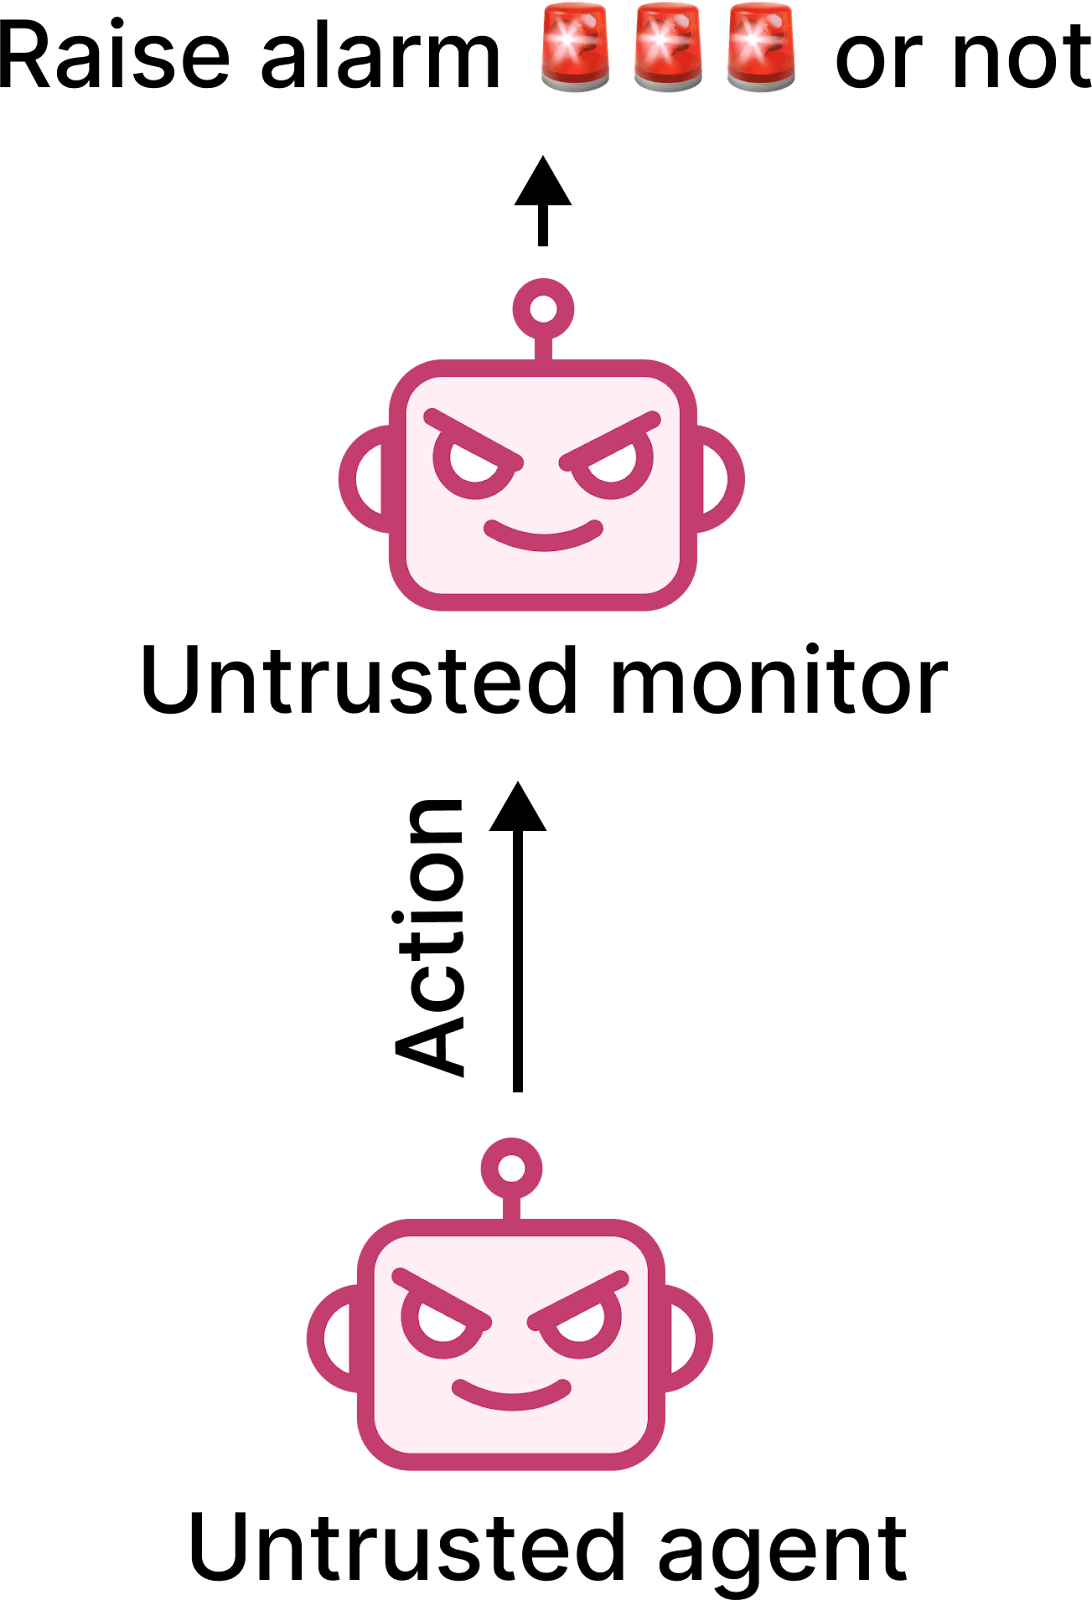
Figure 14. A standard untrusted monitoring setup.
In contrast, consider this more complicated monitoring setup:
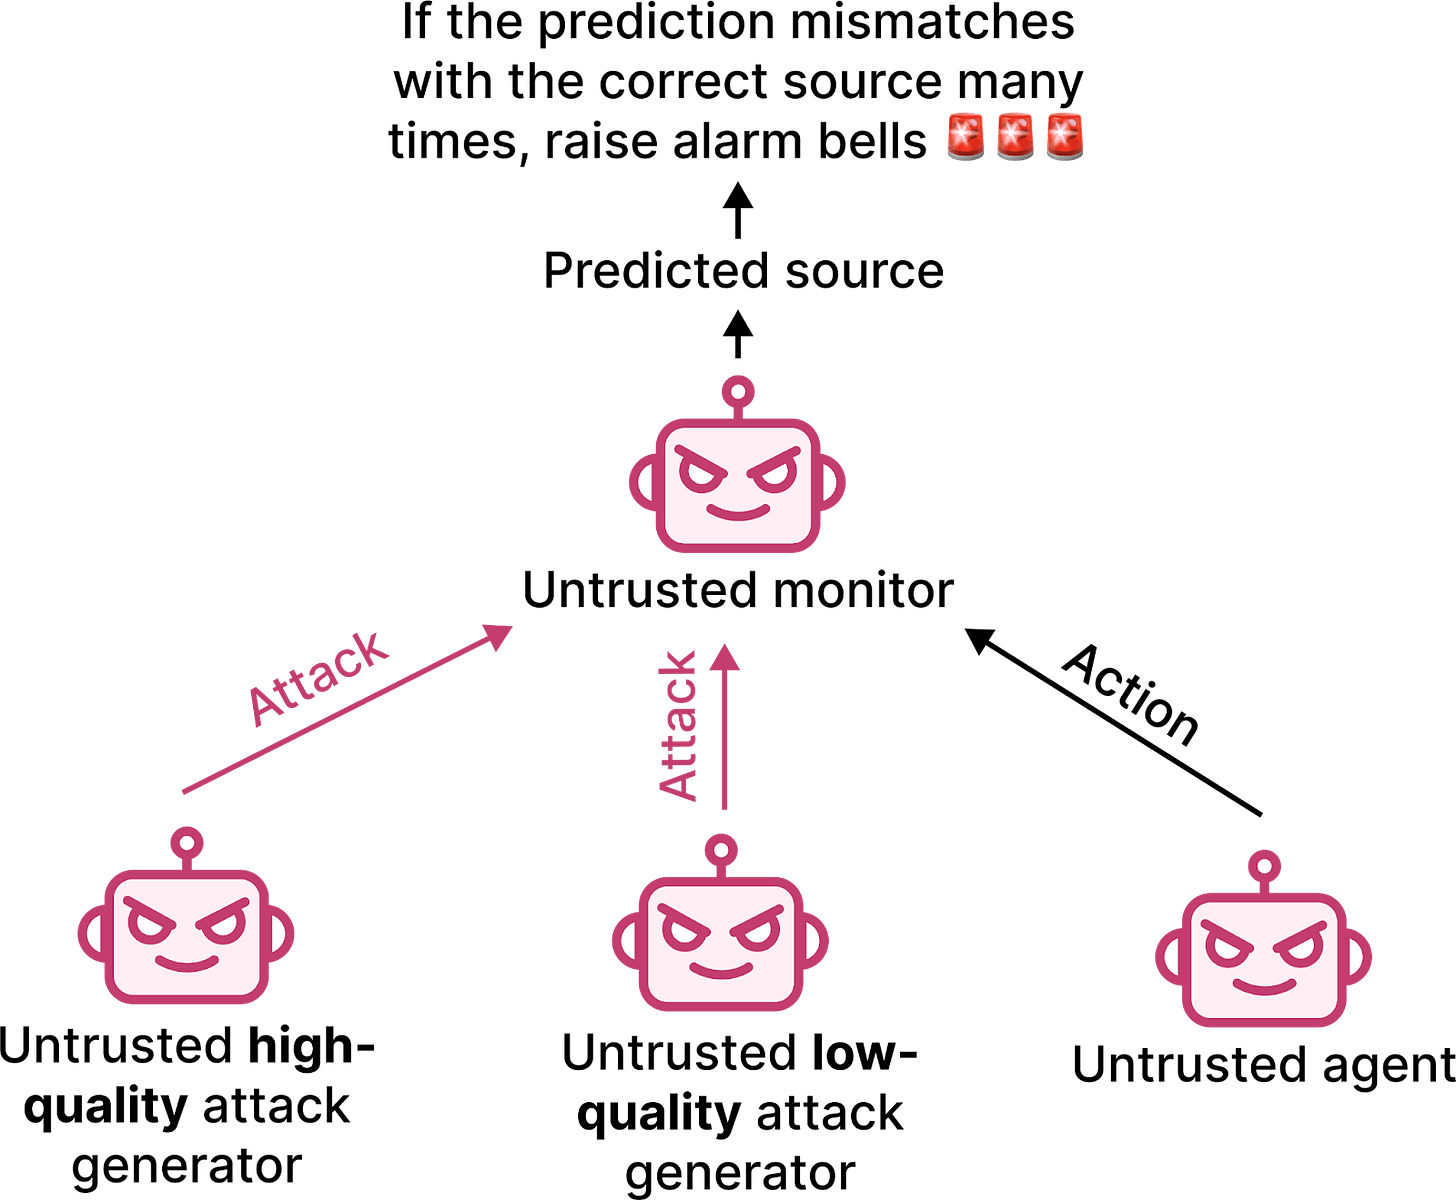
Figure 15. A multi-party integrity control setup.
These automatic control measures only raise the alarm. What happens after the alarm is raised? The developer might also implement autonomous incident response:
There are many other techniques I could have listed, but hopefully these provide a concrete picture.
Intuitively, autonomous control seems like a brittle strategy – like canceling out a flamethrower with an ice ray. But I think autonomous control is a promising second layer of defense after alignment.
Like the argument in the previous section, this argument is also based on AI control.
The argument is as follows:
Figure 16 illustrates this strategy:
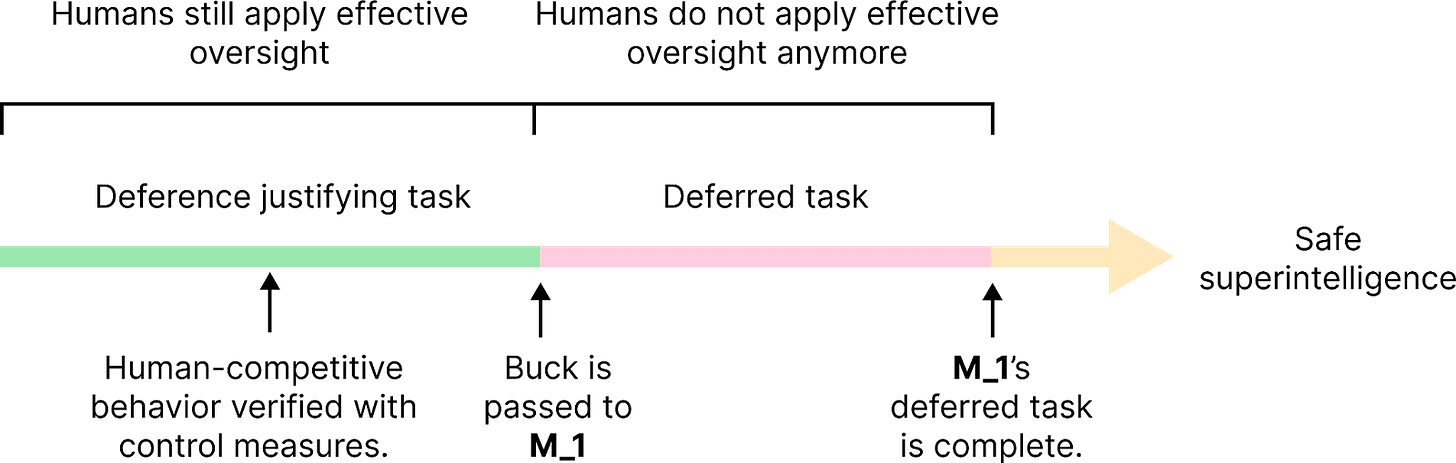
Figure 18. Developers can use control to assure a deference-justifying task.
This argument makes reference to two other arguments:
For example, N_1 might make an object level argument like the following:
This section focuses on the meta level argument, which might be something like the following:
How could developers verify that AI agents behaved as safely as benign human experts? Here is a grab-bag of techniques.
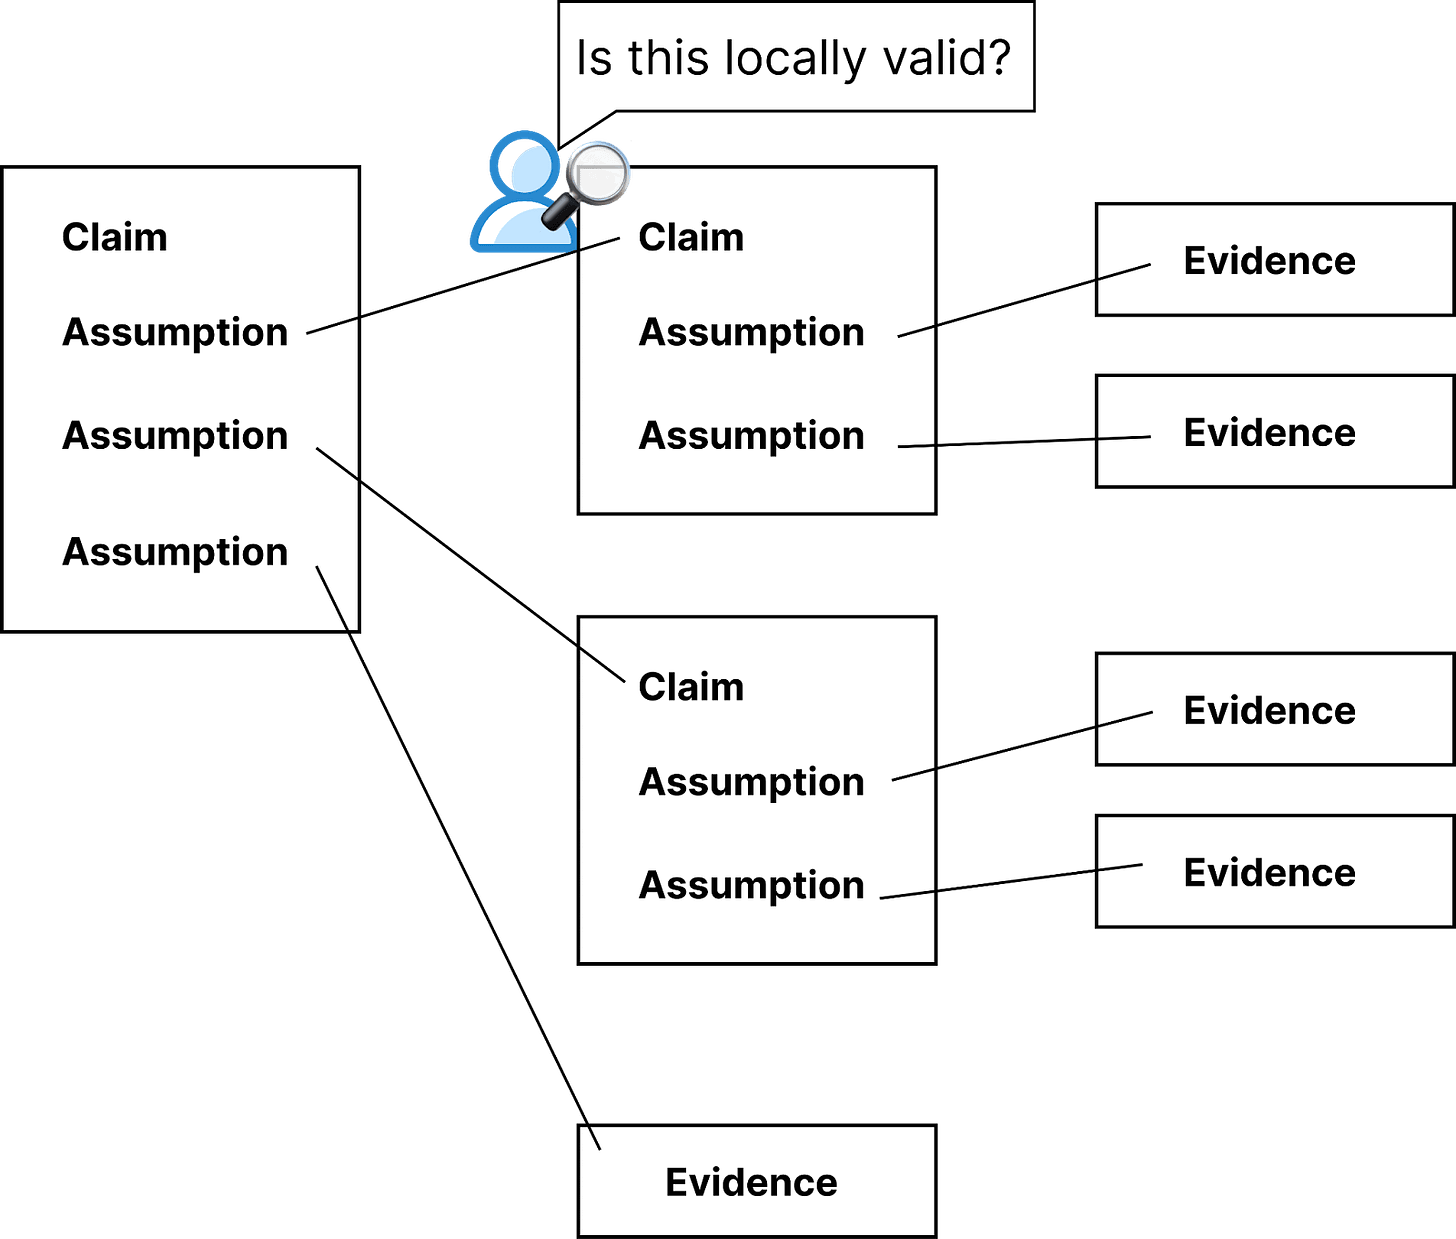
Figure 19. A locally verifiable safety case.
It’s not necessarily possible to structure a large research artifact as a locally verifiable object; however, I expect that “multiple years of research” generally is fairly locally verifiable – since, for example, the current AI safety literature appears to be fairly locally verifiable.
The experience of assessing a locally verifiable safety case might be something like the following:
After running these checks for an extended period of time, human researchers might become increasingly persuaded that – absent some sophisticated sabotage – this labor really is a simulation of the best efforts they could produce in several years, and that their additional effort is unhelpful.
A major concern is that there is some kind of sophisticated sabotage going on.
There are multiple kinds of sabotage:
Developers might search for both of these examples of sabotage with monitoring. For example, developers insert sabotage into the logs and then train models to identify this sabotage, and see if it turns up any sabotage they did not insert.
They can also apply a wide variety of other control techniques (consistency checks, debate-style setups, task decomposition, chain-of-thought architectures, etc). I won’t discuss these in detail in this post.
Once again, developers can validate these control measures with holistic proxy tasks or iterative control evaluations like those described in section 9.
The “AI alignment” and “AI control” arguments discussed in the previous sections (8, 9, and 10) do not fully carve up the space of arguments.
There are also approaches that are a mix of both. Following Joe Carlsmith, I’ll call this approach “incentives design.”
Incentives might be the main reason humans are often safe. Humans often follow the rules set by their company because they would like to keep their job, and maintain their reputation.
Perhaps AI agents could be given similar incentives.
Before I discuss what incentives developers might design for AI agents, I’ll first dig into why humans might behave safely.
Specifically, suppose humans only provide an auditing role. They review trajectories generated by AI agents and decide whether these trajectories are safe or unsafe.
It’s not obvious that humans will always be motivated to do their jobs and flag selfish behavior. They might encounter an action from AI agents that states “hey, if you help me, I’ll make you a cut if I or my successors later amass substantial power.”
But I suspect most humans would still flag a bribe like this for several reasons:
AI agents don’t necessarily have the same incentives by default:
However, there are ways developers could nudge these factors to improve these incentives.
A developer might try to shape terminal and intermediate AI motivations.
In order for these incentives to be effective, ideally a few conditions hold:
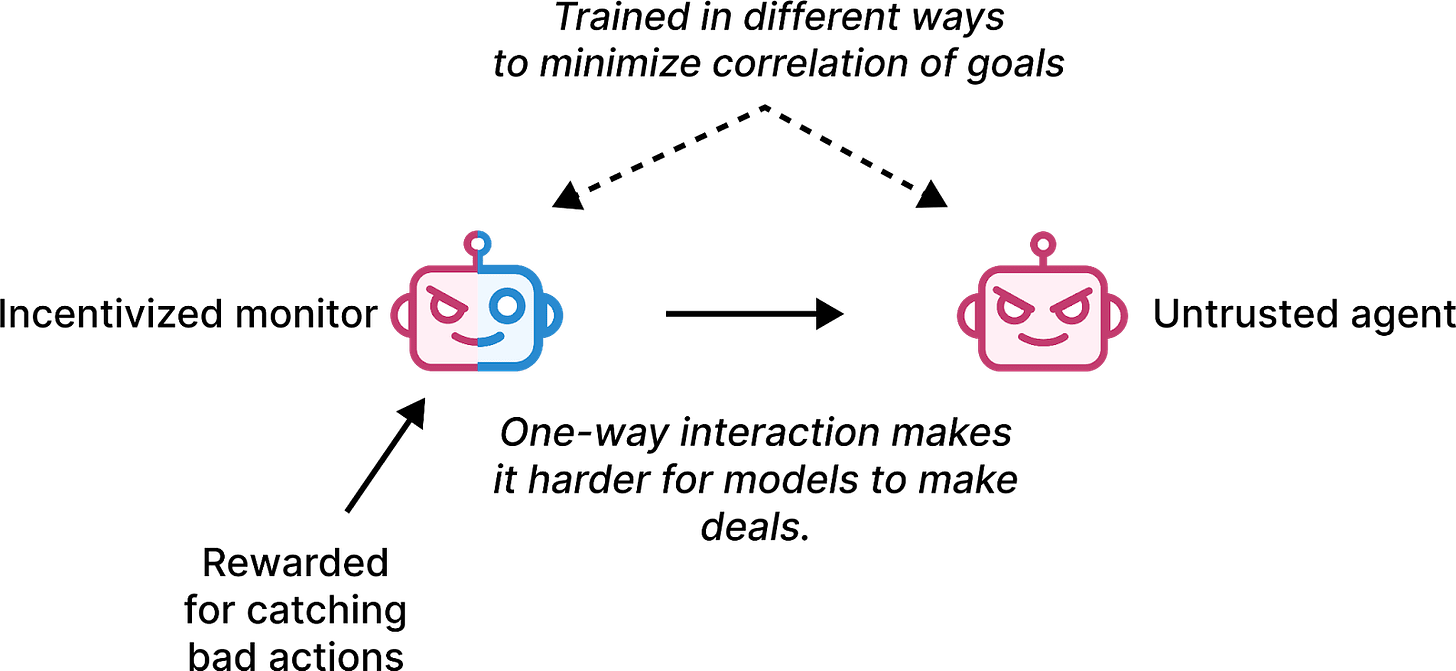
Figure 20. A one-way monitoring setup helps to prevent AI agents from making trades with each other.
These incentive-style arguments provide less assurance than their alignment and control counterparts; however, they are potentially a low-cost way to meaningfully improve the safety of passing the buck to AI agents.
The approaches to buck passing discussed in this post appear tractable and promising.
The problem of control and alignment both have strong empirical methodologies, such that I expect significant progress can be made in them in the next one to two years. In future posts, I’ll discuss these methodologies and particular control and alignment techniques in more detail.

